
ByteDance's Seedance 2.0 Video Generation Model Integrates into Doubao Platform
ByteDance's Seedance 2.0, a video generation model, has been officially integrated into the Doubao application, desktop version, and web platform. The model supports text-to-video, image-to-video, and avatar video functionalities, alongside sound effect generation. Users can access Seedance 2.0 through the Doubao chat interface to generate 5-second or 10-second videos. The platform also offers an "Avatar Video" feature, which requires real-person verification to create a personalized video avatar.
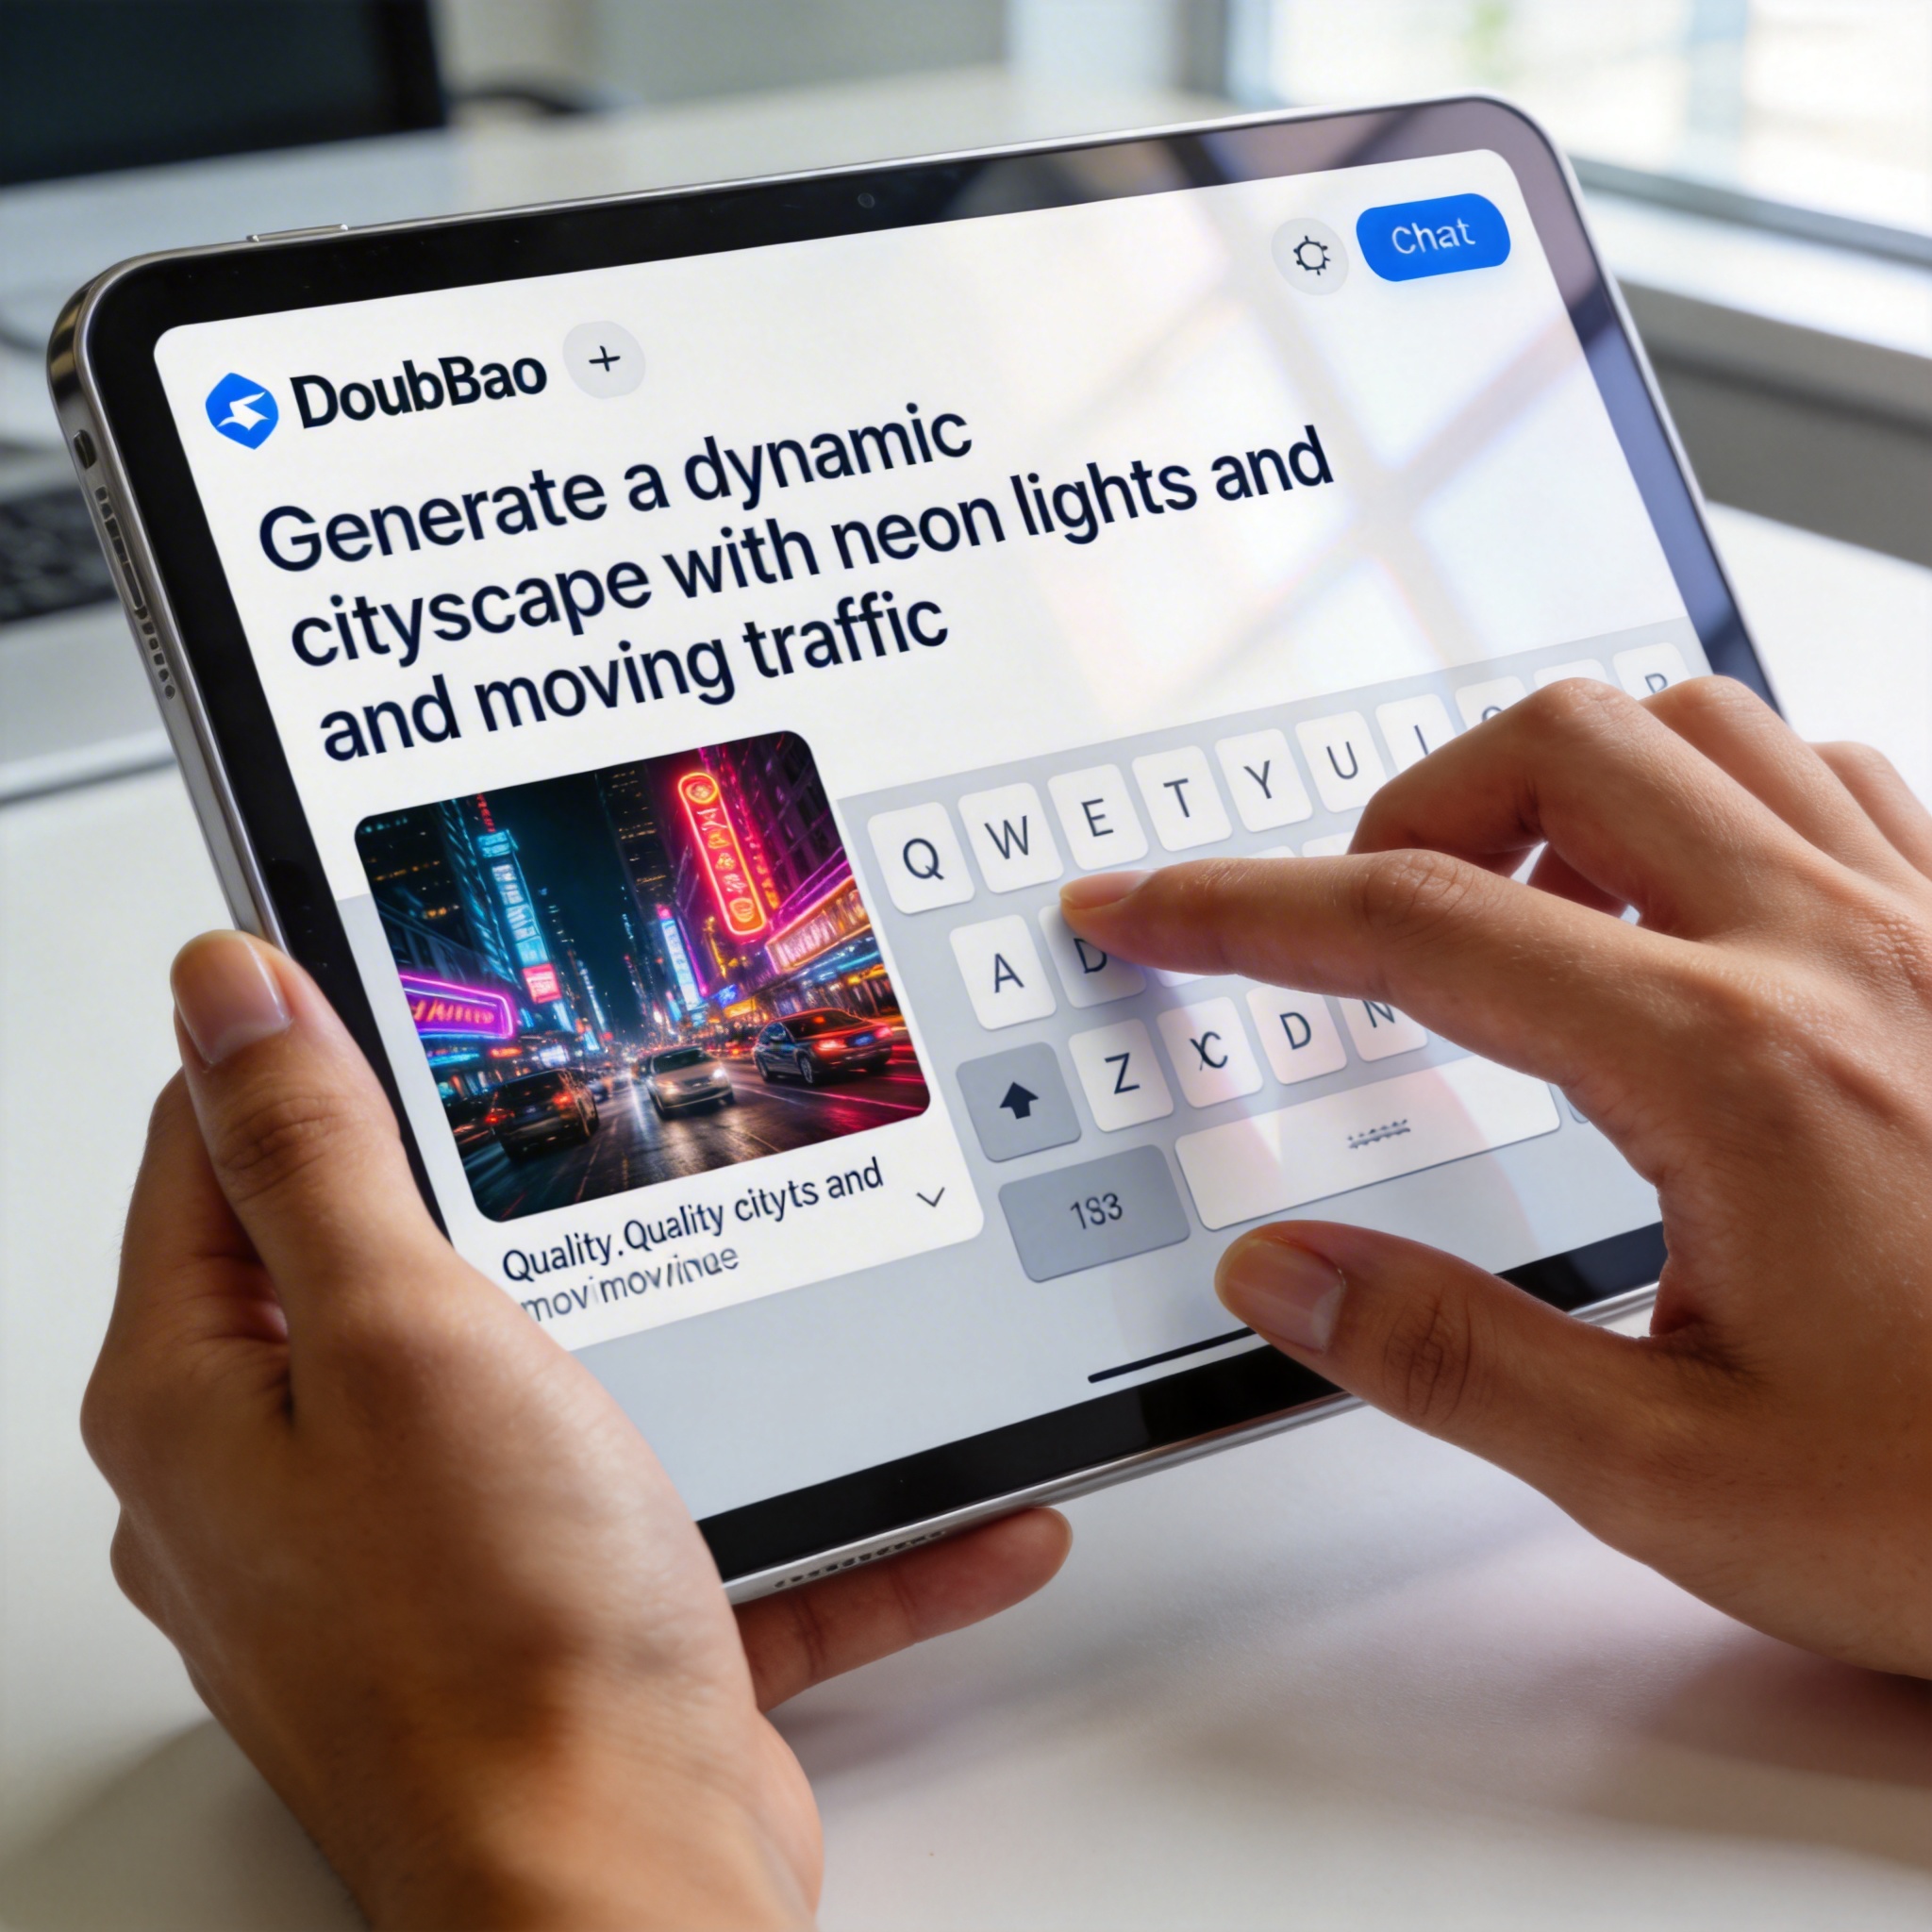
Hands typing a text-to-video prompt on a tablet displaying the Doubao app interface with a video preview.
Text-to-Video Capabilities
Seedance 2.0 allows users to generate videos directly from a single-sentence scene description. The model is designed to produce natural movements and coherent camera transitions, avoiding the artificial appearance often associated with AI-generated video. It can handle complex scenarios, including multi-person interactions and multi-shot transitions, with a generation quality described as among the top tier for current video models.
For example, users can prompt the system to create a multi-scene transitional city documentary. A sample prompt provided includes: "Shoot a multi-scene transition city documentary, starting with red lanterns hanging in an an alley, then queuing up to buy New Year's goods on Huaihai Road, and finally frying spring rolls in the kitchen. Add narration and Shanghai dialect dialogue, with a retro filter."
Another example demonstrates the model's ability to generate imaginative scenarios, such as a fictional fight between Elon Musk and Mark Zuckerberg. The suggested prompt for this scenario details specific character costumes and dialogue: "An intense fight between Elon Musk (in Nezha's costume, but with a face shape and hair color resembling Musk) and Mark Zuckerberg (in Ao Bing's costume, but with a face shape and hair color resembling Zuckerberg), in the style of the Nezha animation, similar to the classic battle scene between Nezha and Ao Bing, but with the characters replaced. Musk: My XAI is number one in the world! Zuckerberg: No, my alpaca LLAMA is number one in the world!"
Abstract, shimmering digital human silhouette composed of light and data particles, symbolizing an avatar.
Avatar Video Functionality
The avatar video feature enables users to record a short video of themselves to create a digital avatar. This avatar can then be placed into various scenes based on user commands, such as dancing on a snowy mountain or strolling in space. The feature also supports combining avatars with reference photos.
An example prompt illustrates this capability: "Help me generate an avatar video: my younger self (Image 2) giving a speech at Ted2026: '2026 is a year of explosive growth for AI Agent applications, truly helping humanity work and improve efficiency.' Followed by applause and interaction. Original aspect ratio, duration 10s, model 2.0."
Another example shows an avatar interacting with a past version of oneself: "Help me generate an avatar video: my working self (Image 2) goes back in time to tell my college self (Image 3): 'Learn English and software engineering well, they will be very useful in the future'; my college self looks at me in disbelief: 'Who are you?' My working self smiles and replies, 'Your AI avatar. Oh, and remember to buy Nvidia stock.' Original aspect ratio, duration 10s, model 2.0."
This avatar functionality addresses the need for content creators to produce personalized video content without requiring their physical presence for every shoot. It aims to balance personal recognition with production flexibility.
Content creators collaborating in a modern studio, reviewing video content on a large screen and tablets.
Additional Features and Usage
Beyond text-to-video and avatar video, Seedance 2.0 includes support for multi-image-to-video generation, allowing users to upload character and background images to create story videos. The model also offers video partial editing and style transfer capabilities, indicating enhanced controllability compared to its predecessor. The integration into Doubao is designed for ease of use, resembling a chat conversation where users upload materials and specify their desired output. For privacy and portrait protection, Doubao Seedance 2.0 does not currently permit the uploading of real-person images as the primary reference.
Stay Ahead of the AI Curve
Join 50,000+ subscribers getting the latest AI tools, trends, and tutorials delivered to their inbox weekly.
No spam, unsubscribe at any time.