
Volcano Engine Unveils Seedance 1.5 Pro With Native Audio-Visual Synchronization
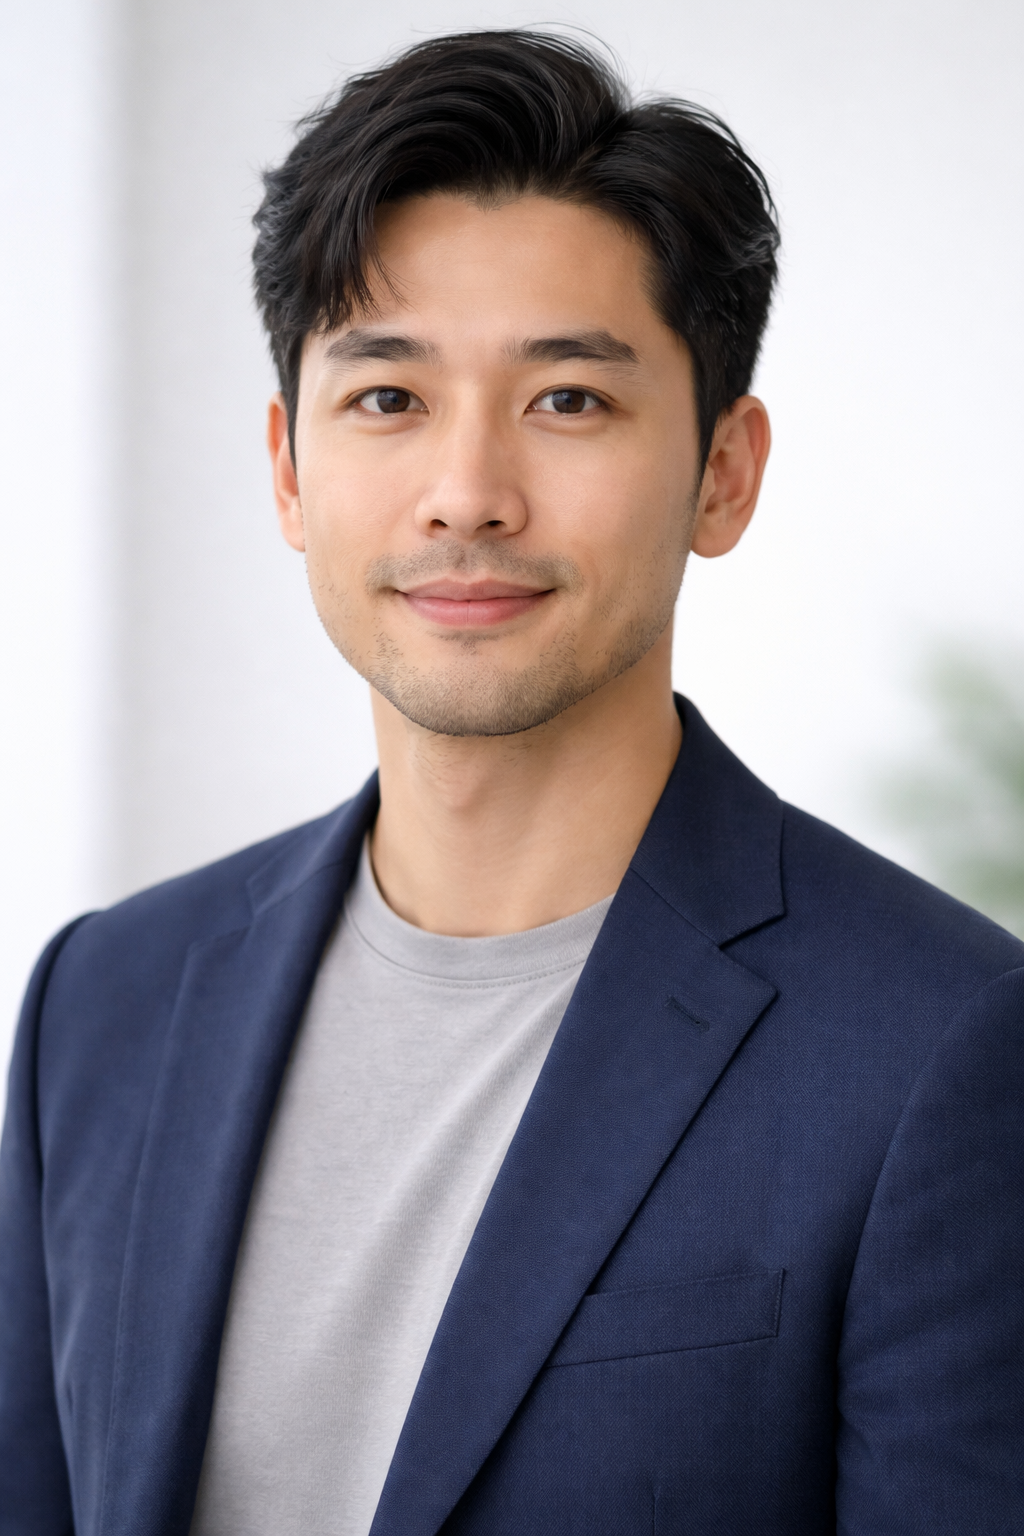
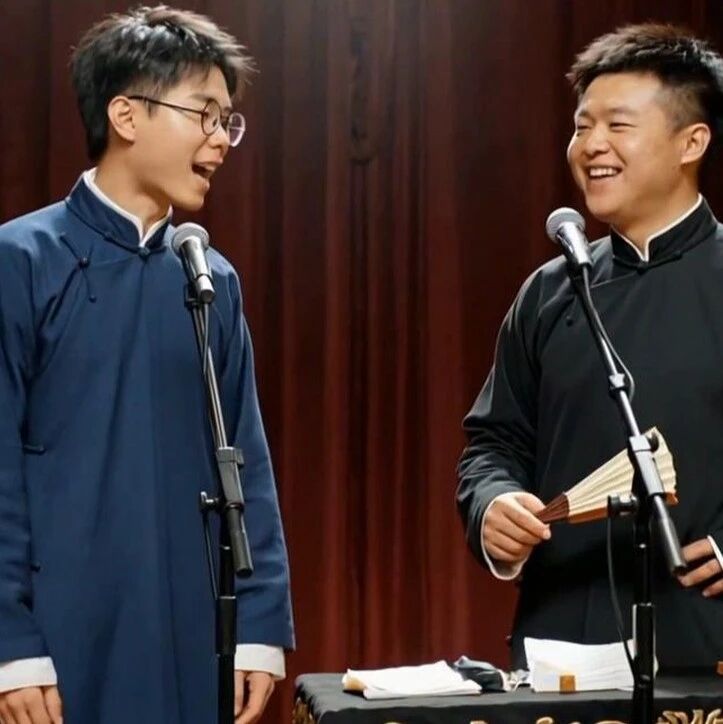
ByteDance’s cloud division, Volcano Engine, has released Seedance 1.5 Pro, a new video generation model engineered for native audio-visual synchronization. Unveiled at the 2025 Winter FORCE Conference, the model introduces integrated sound synthesis capabilities—covering speech, environmental noise, and background music—alongside enhanced instruction following and camera control.
According to Volcano Engine, the model is currently available via the Volcano Ark Experience Center, with enterprise API access scheduled for December 23. Consumer access is provided through the Jimeng web platform and the Doubao application.
Native Audio-Visual Integration
The primary advancement in Seedance 1.5 Pro is its ability to generate video and audio simultaneously within a single workflow. Unlike previous iterations that produced silent video requiring separate audio post-production, the new architecture achieves millisecond-level synchronization between visual elements and sound.
This capability extends to complex dialogue scenarios. The model supports multi-language lip-syncing, covering English, Mandarin, and 16 specific Chinese dialects, including Shaanxi, Sichuan, and Cantonese. In demonstrations reviewed by toolmesh.ai, the model successfully rendered clips of public figures speaking in regional dialects with accurate lip modulation and facial expressions.
Beyond speech, the system synthesizes environmental and mechanical sounds. Tests involving ASMR content—such as typing on a keyboard or blowing into a microphone—demonstrated distinct audio layering that aligned with the visual action. Internal benchmarks cited by Volcano Engine suggest Seedance 1.5 Pro surpasses Google’s Veo 3.1 and Kuaishou’s Kling 2.6 in metrics regarding generation quality, synchronization, and alignment.
Complex Instruction Adherence
A recurring challenge in generative video is the "gacha" effect, where users must generate multiple iterations to achieve a usable result. Seedance 1.5 Pro reportedly mitigates this by improving adherence to complex prompts on the first attempt.
In evaluations involving dynamic scenes, the model maintained logical consistency across varied camera movements and lighting conditions.
Narrative Control: In a test involving a dialogue between a host and a tourist on a busy street, the model managed handheld camera shake, depth-of-field changes, and natural conversational pauses without breaking visual continuity.
High-Speed Dynamics: Sequences depicting an F1 car on a Monaco circuit and a WWI soldier running through a battlefield utilized motion blur and grain to simulate specific cinematic textures, maintaining physical coherence during rapid movement.
Commercial Applications: The model interpreted abstract instructions for a Tesla advertisement, transitioning from a minimalist box to a fully assembled showroom, strictly following prompts regarding lighting shifts and spatial assembly.
Technical Architecture
The technical report associated with the release indicates that Seedance 1.5 Pro utilizes a unified modeling framework based on the MMDiT architecture. This design allows for deep cross-modal interaction, ensuring that visual and auditory signals remain synchronized in the time dimension.
The training pipeline involved three distinct stages:
Joint Pre-training: The model was trained on large-scale mixed-modal datasets to establish a foundation for text-to-audio-video and image-to-audio-video tasks.
Supervised Fine-Tuning (SFT): High-quality datasets were used to refine specific generation capabilities.
Reinforcement Learning from Human Feedback (RLHF): The team applied RLHF algorithms customized for audio-video scenarios, utilizing multi-dimensional reward models to optimize motion quality and audio fidelity.
To address inference latency, Volcano Engine implemented a multi-stage distillation framework. Combined with quantization and parallel computing optimizations, this approach reportedly achieved a ten-fold increase in end-to-end inference speed compared to previous iterations.
Market Implications
The release of Seedance 1.5 Pro marks a shift from video-only generation to comprehensive content production. By integrating sound and improving "one-shot" generation reliability, the model aims to support professional workflows in advertising and short-form drama production.
Industry observers note that the sector is moving toward "production-grade" tools capable of handling complex storyboards and character consistency. While earlier models functioned primarily as experimental tools, the integration of native audio and precise camera control suggests a trajectory toward full-pipeline video automation.
Stay Ahead of the AI Curve
Join 50,000+ subscribers getting the latest AI tools, trends, and tutorials delivered to their inbox weekly.
No spam, unsubscribe at any time.