
Prompt Repetition Significantly Boosts Non-Reasoning LLM Accuracy, Google Research Shows
A recent Google study has revealed that simply repeating a prompt can dramatically improve the accuracy of non-reasoning large language models (LLMs), with some models seeing accuracy rates jump from 21.33% to 97.33%. The technique, detailed in a paper titled "Prompt Repetition Improves Non-Reasoning LLMs," involves duplicating the original query.
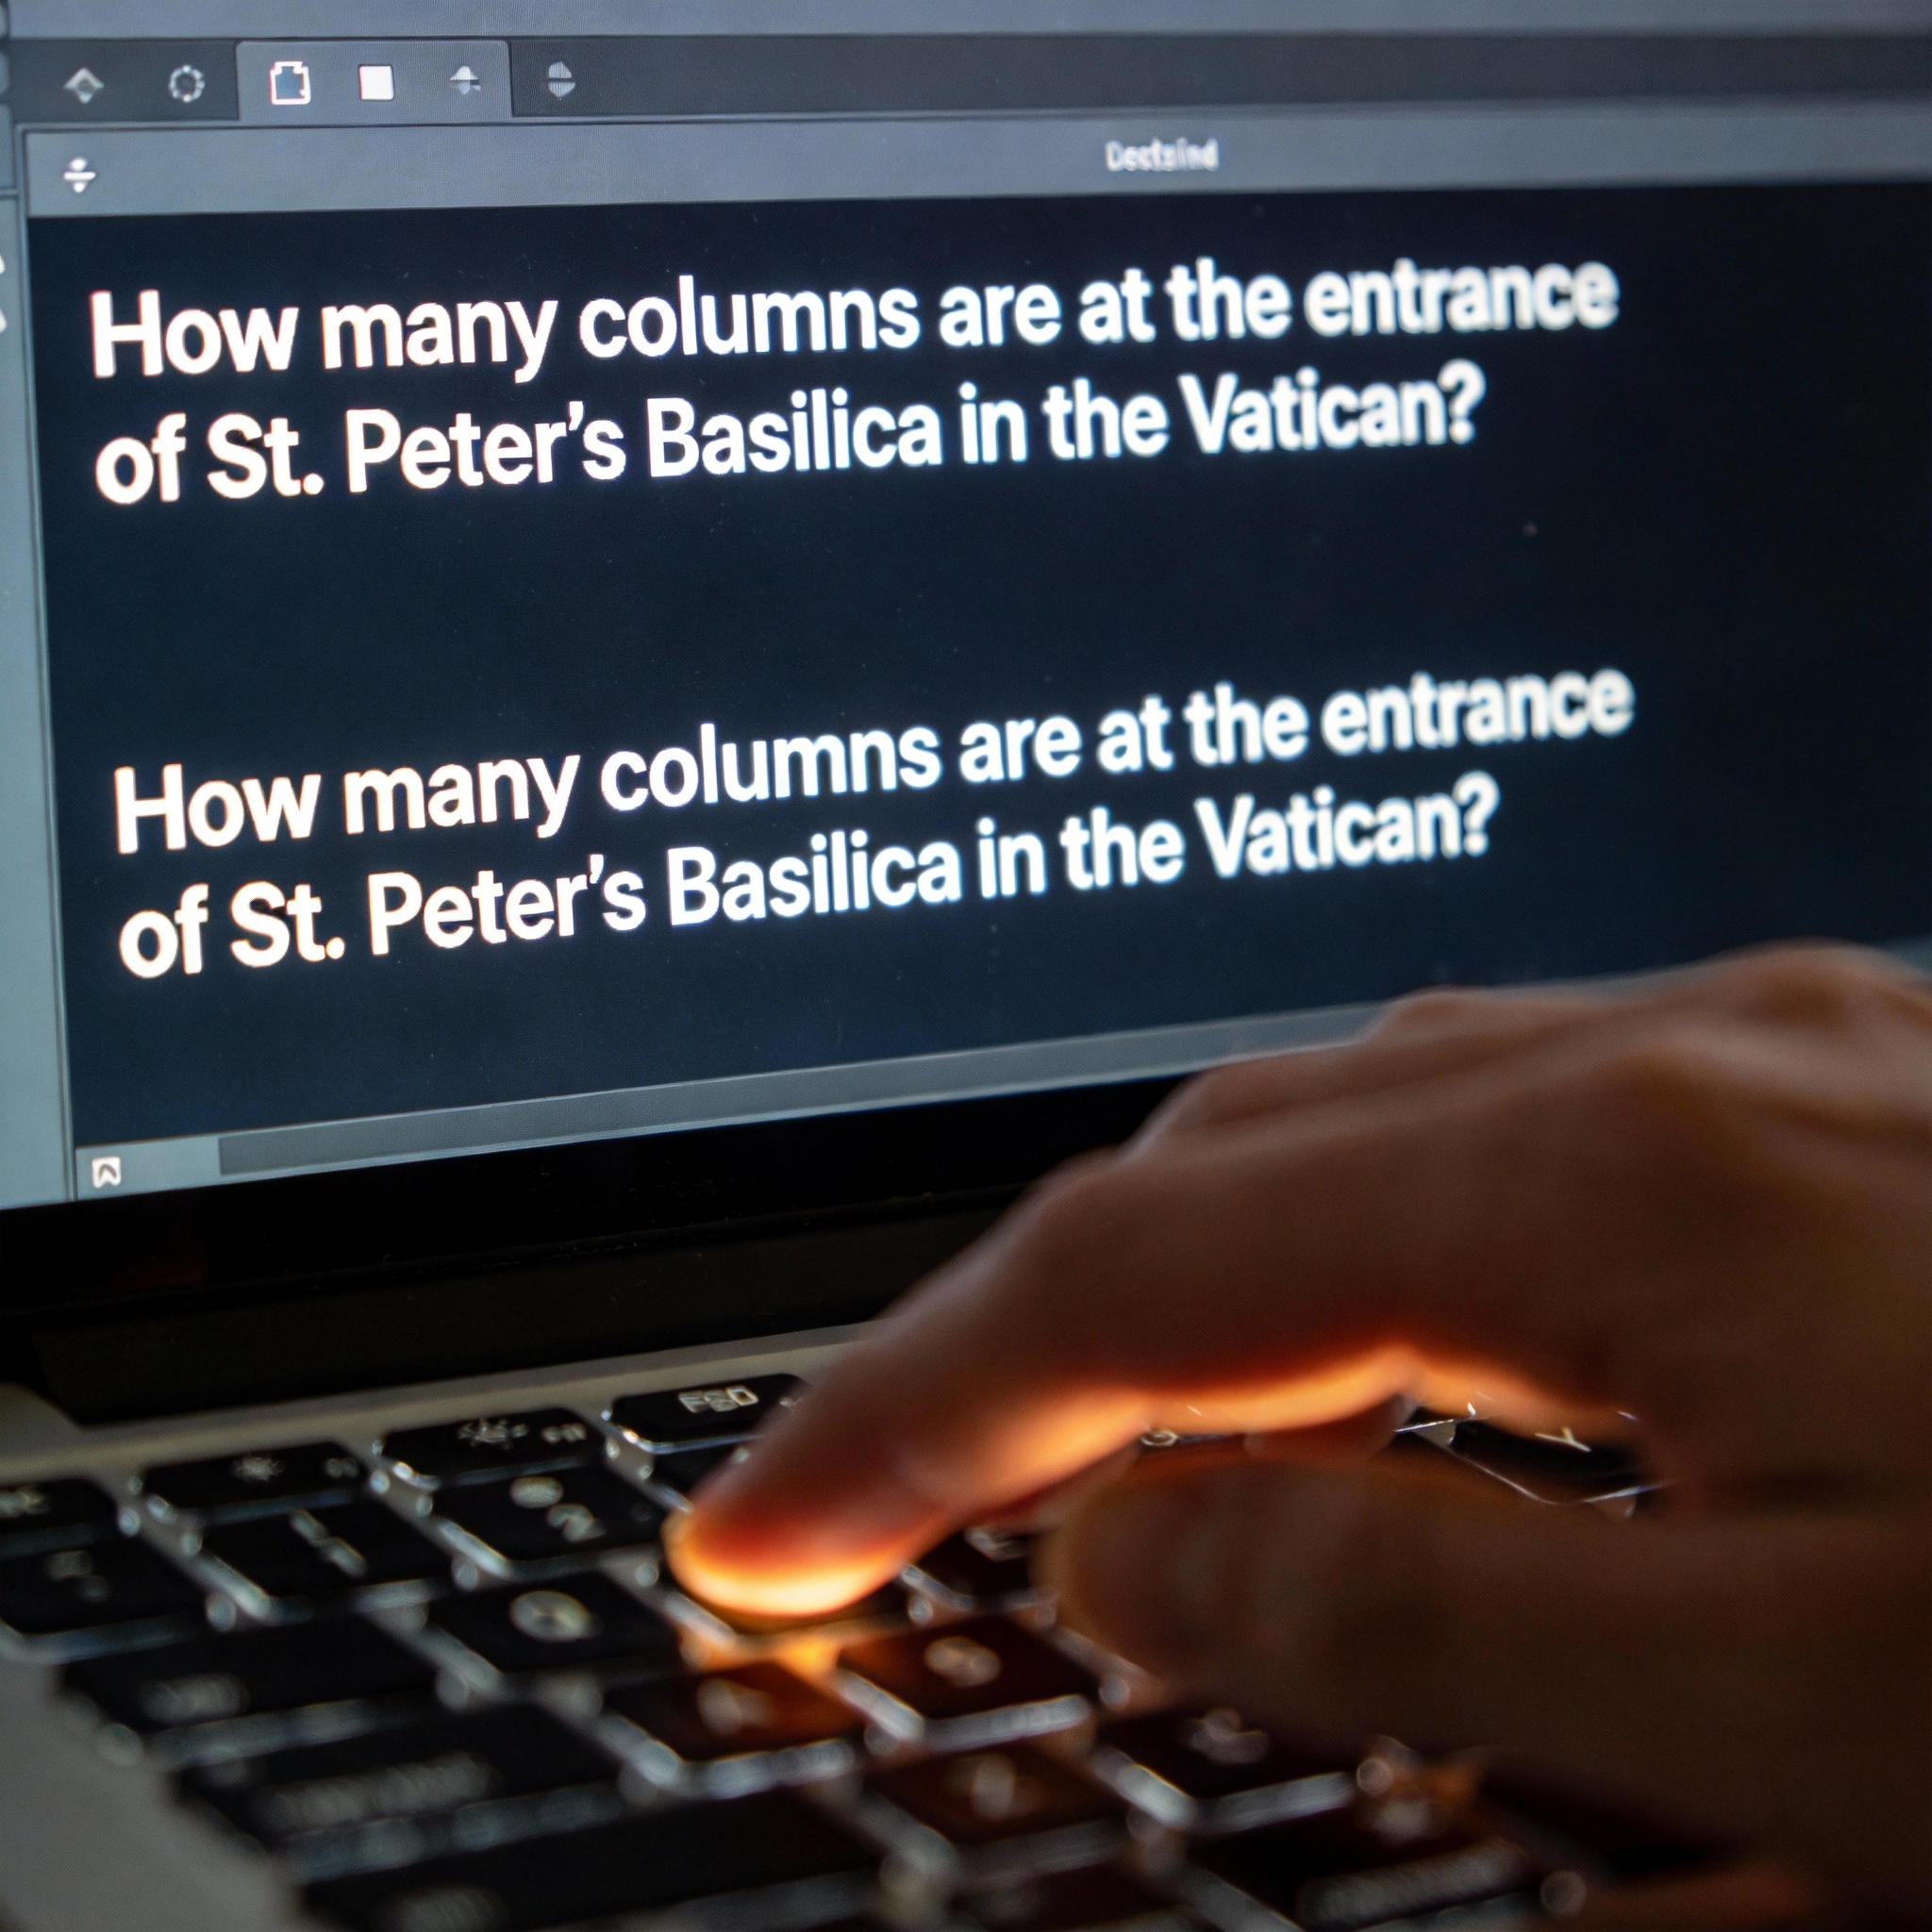
Computer screen showing a question repeated twice, illustrating prompt repetition.
For instance, a question like "How many columns are at the entrance of St. Peter's Basilica in the Vatican?" becomes "How many columns are at the entrance of St. Peter's Basilica in the Vatican? How many columns are at the entrance of St. Peter's Basilica in the Vatican?" This method, essentially a "copy-paste" approach, proved effective across various benchmarks.
Experimental Findings and Model Types
Google's research tested seven prominent non-reasoning models: Gemini 2.0 Flash and Flash Lite, GPT-4o and 4o-mini, Claude 3 Haiku, 3.7 Sonnet, and DeepSeek V3. These models were evaluated using official APIs across standard benchmarks such as ARC, OpenBookQA, GSM8K, MMLU-Pro, and MATH, alongside two custom tests, NameIndex and MiddleMatch. NameIndex involved identifying the 25th name in a 50-name list, while MiddleMatch required finding a name between two characters in a randomly repeating list.

Conceptual split image contrasting a fast, streamlined non-reasoning AI with a complex, deliberative reasoning AI.
The study found that prompt repetition was particularly beneficial for non-reasoning models. Reasoning models, which engage in active thought processes and chain-of-thought reasoning, often inherently rephrase or restate questions as part of their internal process. Non-reasoning models, designed for speed over complex deliberation, typically benefit more from this external repetition.
Performance Gains and Methodology
In 70 different test tasks, the copy-paste method outperformed single-prompt queries 47 times and never resulted in a decrease in performance. All tested models showed improved performance. The technique involved simply appending an identical copy of the original question without any additional instructions or formatting. Further experiments also indicated that repeating the prompt three times could yield even greater improvements.
Explaining the Phenomenon
The paper offers an engineering-centric explanation rooted in how causal language models process information. These models predict tokens sequentially, from left to right, with each token's computation relying only on preceding tokens. When a prompt is repeated, the second instance of the question allows the model to "look back" at the full context of the first instance.
Abstract visualization of sequential token processing in a causal language model, with a 'look back' mechanism.
Consider a multiple-choice question where the options precede a scenario description. In a single-prompt query, the model processes options A and B without the full context of the scenario. When the scenario description appears, the initial interpretation of the options cannot be retroactively updated. However, with a repeated prompt, the second presentation of options A and B occurs after the model has processed the scenario description from the first prompt. This enables the model to form a more informed representation of the options, leading to higher accuracy. This process is akin to re-reading a complex text to gain a deeper understanding.
Future Directions and Broader Implications
The researchers suggest several avenues for future work, including integrating prompt repetition into model training, optimizing KV cache usage for repeated prompts, and exploring partial prompt repetition. The concept also extends to multimodal contexts, such as images and videos.
The findings challenge conventional notions of prompt engineering, which often emphasize elaborate structures and detailed instructions. For many straightforward question-and-answer scenarios, simple repetition proves to be a highly effective, yet often overlooked, optimization. This principle, the study notes, mirrors human cognitive processes where repetition aids understanding, memorization, and emotional reinforcement across various domains.
Stay Ahead of the AI Curve
Join 50,000+ subscribers getting the latest AI tools, trends, and tutorials delivered to their inbox weekly.
No spam, unsubscribe at any time.