
LMArena Secures $150 Million, Reaching $1.7 Billion Valuation for AI Evaluation Platform
LMArena, an AI evaluation platform that allows users to compare and vote on AI models, has raised $150 million in new funding, bringing its valuation to $1.7 billion. The company, which originated as an open-source project at the University of California, Berkeley, has grown to become a prominent crowdsourced benchmarking tool in the AI industry.
Holographic data visualization on a modern conference table, symbolizing funding and valuation growth.
The funding round was co-led by Felicis and the investment arm of the University of California, with participation from Andreessen Horowitz, The House Fund, LDVP, Kleiner Perkins, and Lightspeed Venture Partners. This latest investment follows a $100 million seed round in May 2025, which valued the company at $600 million. Total funding for LMArena now exceeds $250 million.
Evolution from Academic Project to Industry Benchmark
LMArena began in 2023 as Chatbot Arena, an open-source initiative from the Sky Computing Lab at UC Berkeley. Founded by Professor Ion Stoica (a co-founder of Databricks) and graduate students Anastasios Angelopoulos (now CEO) and Wei-Lin Chiang (now CTO), the project initially aimed to enable anonymous comparisons of AI chatbots by general users.
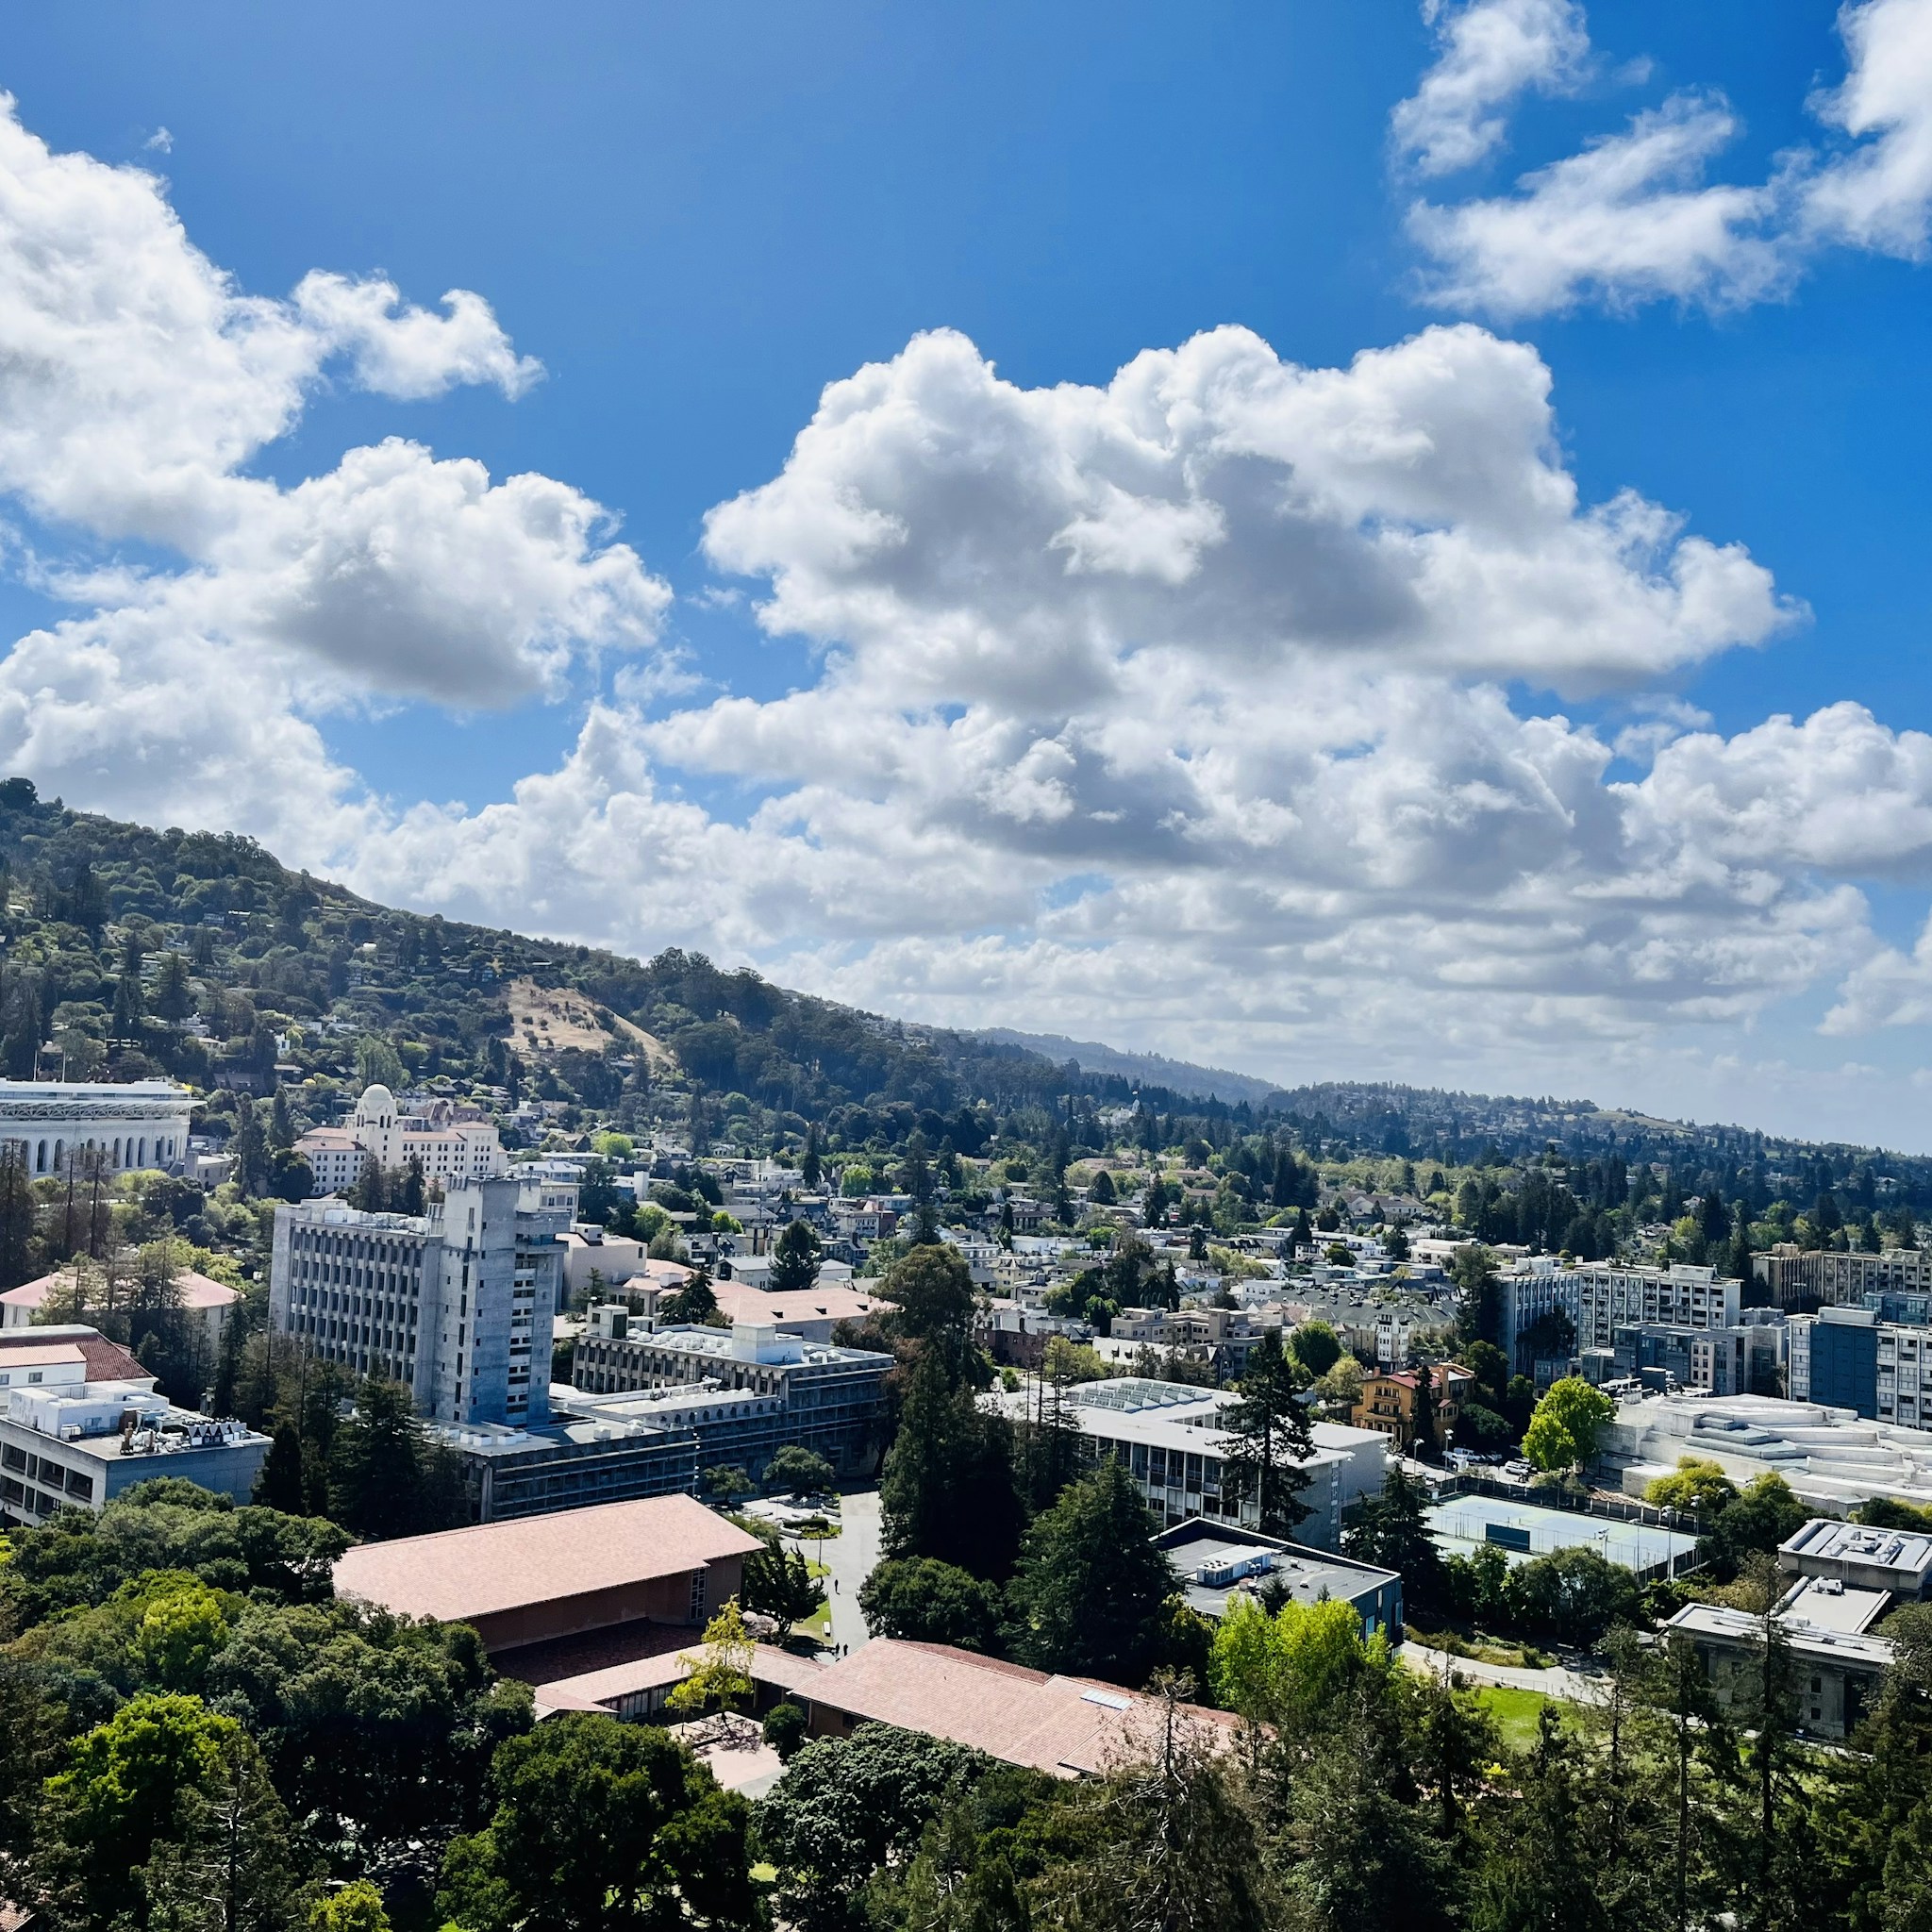
Aerial view of the University of California, Berkeley campus, with academic buildings and green spaces.
The platform gained rapid traction, transitioning into a for-profit company in May 2025 and rebranding as LMArena. It currently reports over 5 million monthly active users across 150 countries, generating more than 60 million conversations each month. Major AI labs, including OpenAI, Google, xAI, and Microsoft, reportedly submit their models to the platform for evaluation.
Blind Testing and Crowdsourced Ranking System
LMArena's core functionality, known as Arena mode, allows users to submit a query and receive responses from two randomly selected, anonymous AI models. Users then vote for the better response without knowing which model generated it. After voting, the models are identified.
The platform employs an Elo rating system to calculate real-time scores based on user votes, with wins adding points and losses deducting them. Leaderboards are maintained across various categories, including text conversation, web development, visual comprehension, text-to-image generation, image editing, and text/image-to-video generation. Recent rankings show Gemini-3-Pro leading in text and visual domains, with Grok-4.1-thinking also performing strongly. GPT-Image-1.5 and Gemini variants have frequently topped image editing charts.
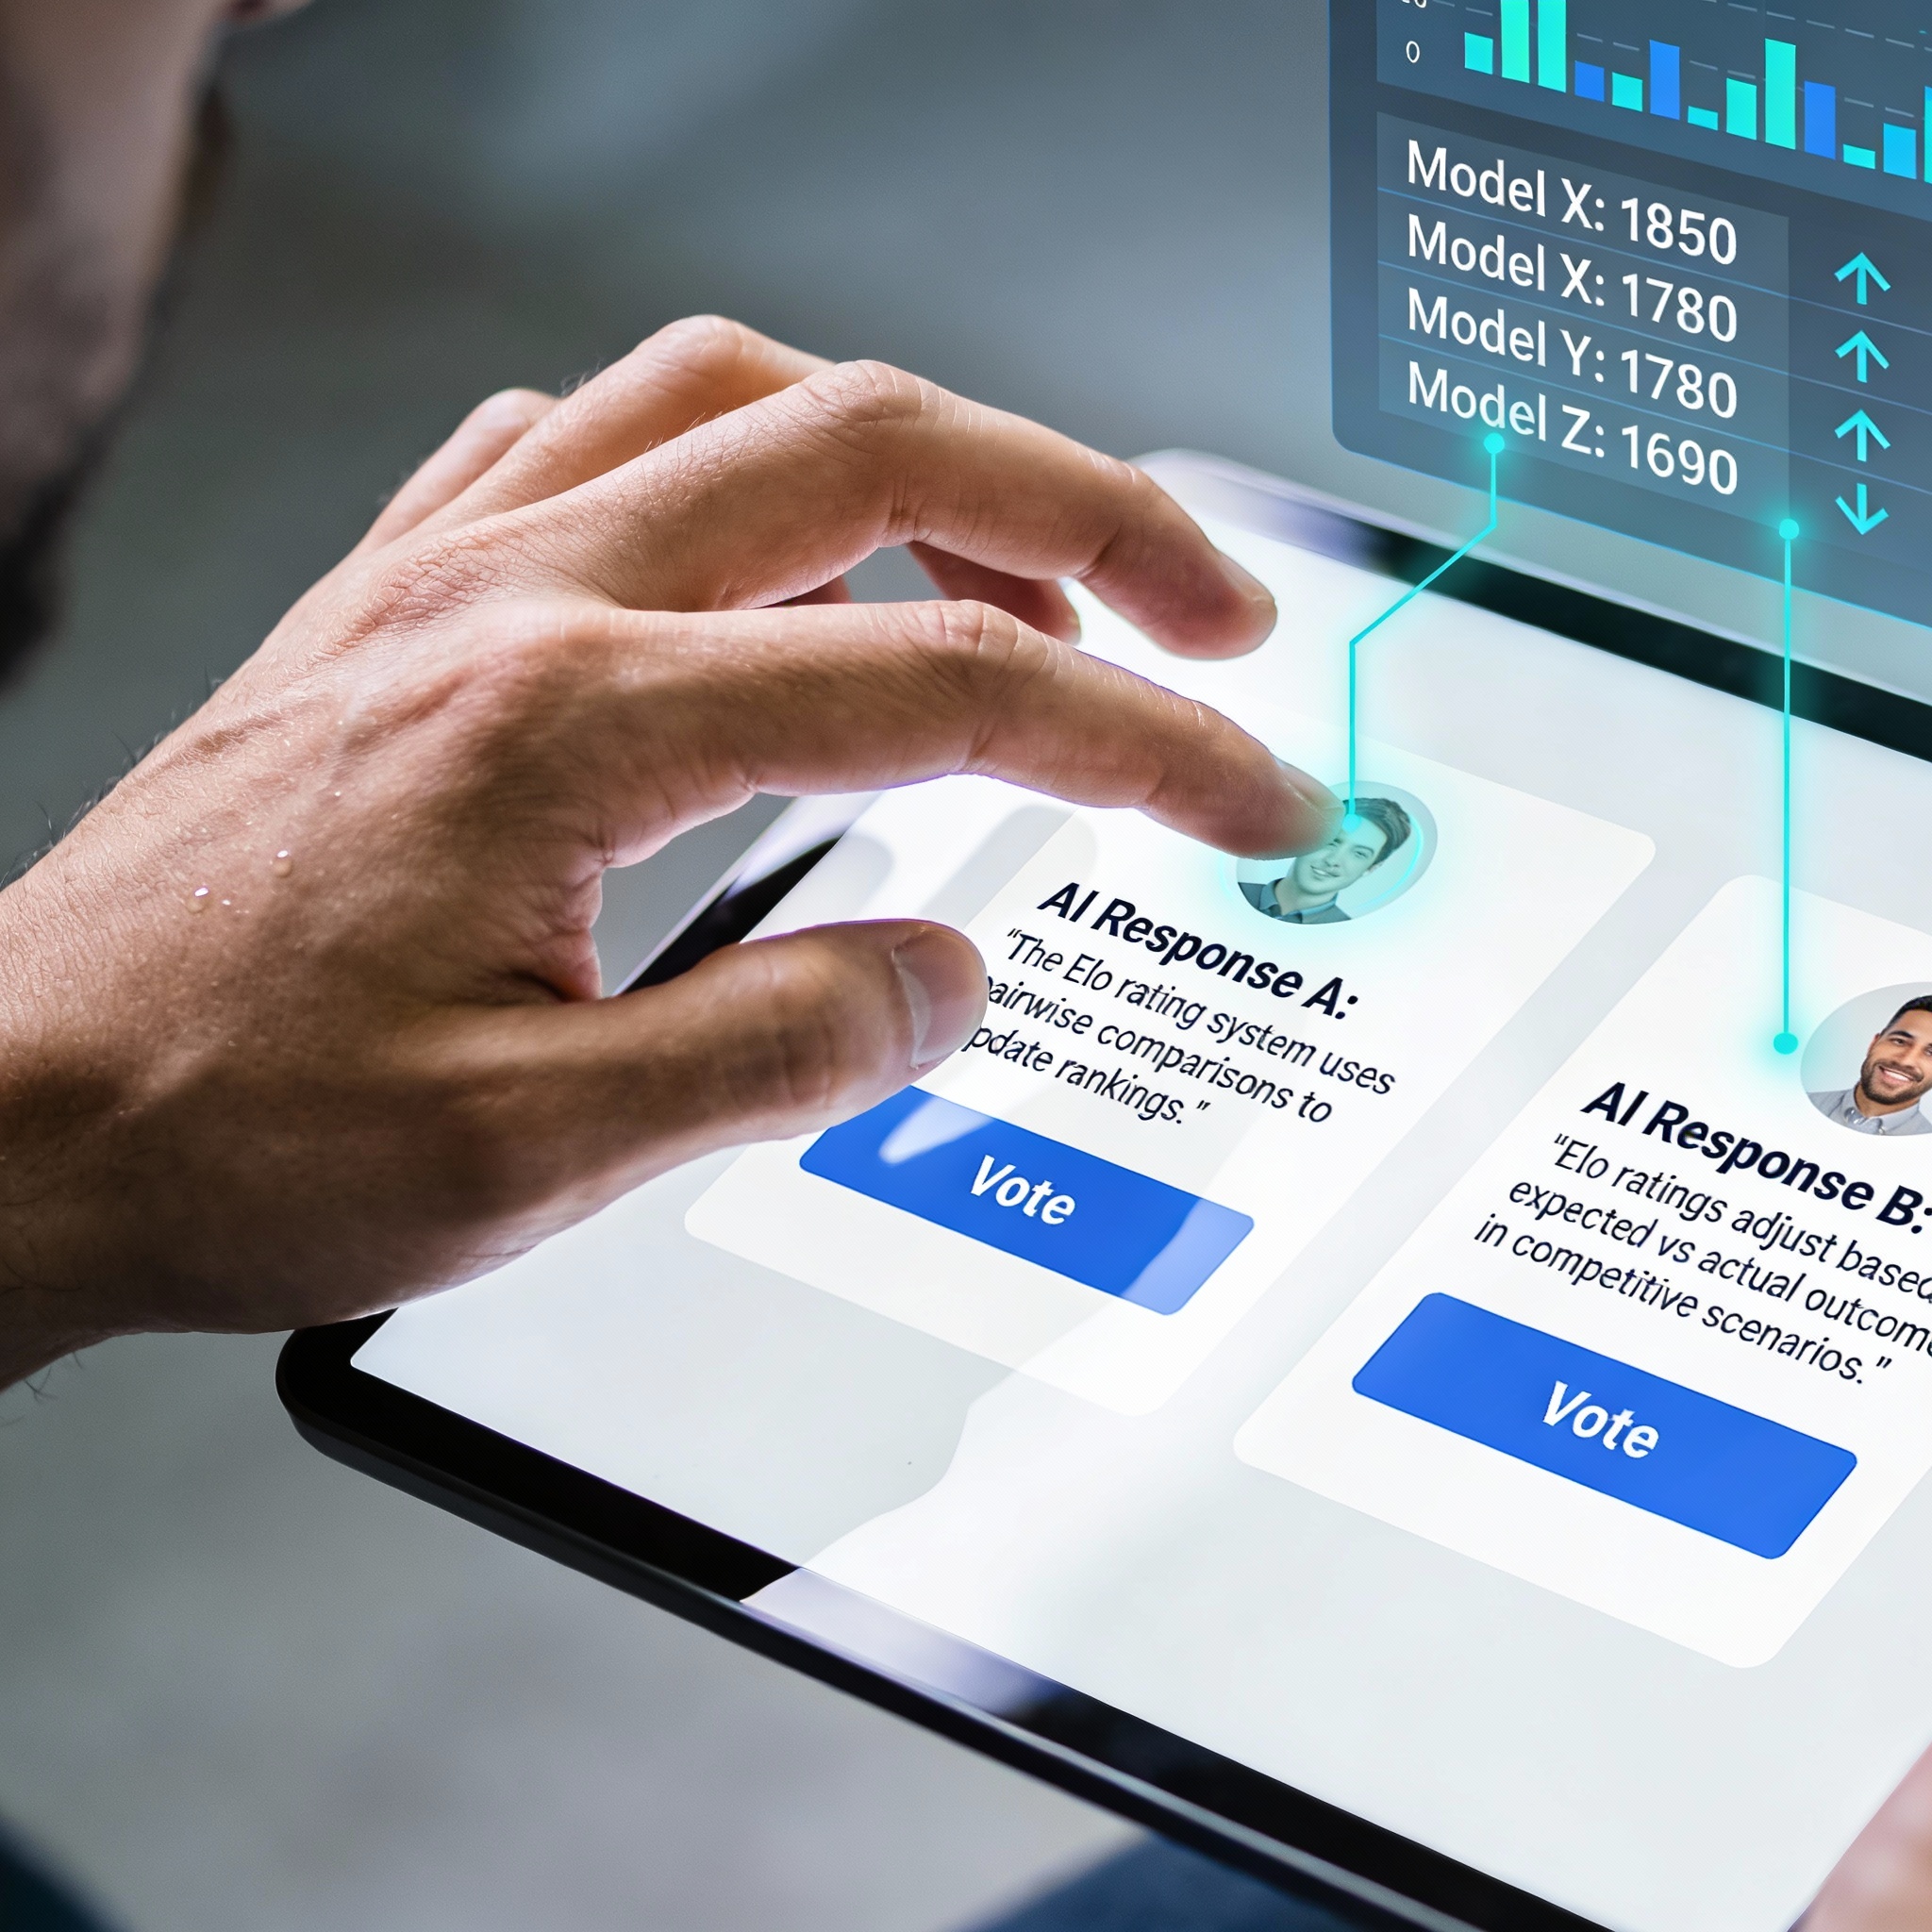
Hands interacting with a tablet displaying an AI model comparison interface with voting options.
CEO Anastasios Angelopoulos stated that leading AI companies utilize LMArena because they find it challenging to assess their own models. Unreleased models are often tested on the platform to gather user feedback for rapid iteration.
Controversies and Future Expansion
Despite its growth, LMArena has faced criticism regarding the potential for manipulation in crowdsourced voting. A 2025 paper alleged that Meta secretly tested 36 private variants of its Llama 4 model on the platform to influence rankings. Researchers from institutions including Cohere, Stanford, and MIT have also suggested that large labs can optimize models through multiple private tests, creating an uneven playing field for smaller entities. Accusations of "ballot stuffing" and biased rankings have also been made.
Abstract digital scale showing an imbalance of data points, symbolizing potential bias in crowdsourced evaluations.
Some critics argue that general user voting lacks the professional rigor of expert evaluations. Competitor Scale AI, for instance, employs paid experts, such as lawyers and professors, to score AI responses. In September 2025, Scale launched its "Seal Showdown" platform, positioning it as a more rigorous alternative to LMArena's crowdsourcing model.
Co-founder Ion Stoica has defended LMArena's approach, stating that user feedback on familiar topics provides the most honest evaluation. He also highlighted the diversity of users from 150 countries as a factor that enhances the comprehensiveness of the rankings.
LMArena plans to use its new funding to expand computing resources, recruit engineers, and launch enterprise-level AI evaluation services. This will include offering paid professional evaluations to major AI companies, providing model testing, feedback collection, report generation, and customized benchmark tests. The company is also exploring the use of its extensive user voting data for reinforcement learning from human feedback (RLHF) to train and optimize AI models.
Diverse team of engineers collaborating in a modern office, working on AI model optimization and enterprise solutions.
Peter Deng, a partner at Felicis, noted that becoming a de facto benchmark layer naturally leads to product expansion, with significant value derived from deep collaboration with AI labs.
Stay Ahead of the AI Curve
Join 50,000+ subscribers getting the latest AI tools, trends, and tutorials delivered to their inbox weekly.
No spam, unsubscribe at any time.