
LibTV Integrates Seedance 2.0 for Enhanced AI Video Production Without Queue Times

LibTV has fully launched Seedance 2.0, an advanced video generation model, enabling users to create complex video content without waiting in line. The integration aims to transform LibTV from a material generation tool into a comprehensive content production platform.
Holographic video editing timeline with automated segment assembly, illustrating Seedance 2.0's capabilities.
The Seedance 2.0 model, now available on LibTV, allows for the direct generation of complete videos from second-by-second scripts. This includes multiple shots, automatic transitions, rhythm control, and synchronized sound effects, dialogue, and ambient audio. Previously, users often had to generate individual shots and manually edit them.
Advanced Narrative Capabilities
Seedance 2.0 demonstrates an understanding of "narrative" beyond simple image generation. For instance, a test involved creating a suspense trailer with editing techniques like quick cuts, slow motion, and sudden shifts in sound. The model successfully interpreted these instructions to produce a video with a "tension → relaxation → burst → silence" rhythm.
Abstract light trails representing dynamic narrative flow and seamless video transitions.
Another feature, Omni-Reference Mode, allows users to generate a video, then use the last five seconds as a reference for the next segment. This creates seamless transitions between clips, enabling the production of longer, continuous narratives. A war movie clip generated using this mode maintained consistent color tones and characters across multiple segments, with synchronized audio and visual effects.
Real-Time Scene Generation
The model also excels at generating dynamic, high-speed scenes. One example involved a single-shot video of a skateboarder navigating a crowded New York City street. Seedance 2.0 accurately rendered complex interactions, such as pedestrians moving independently, taxis with correct relative speeds, and reflections on glass buildings that shifted with the camera's movement.
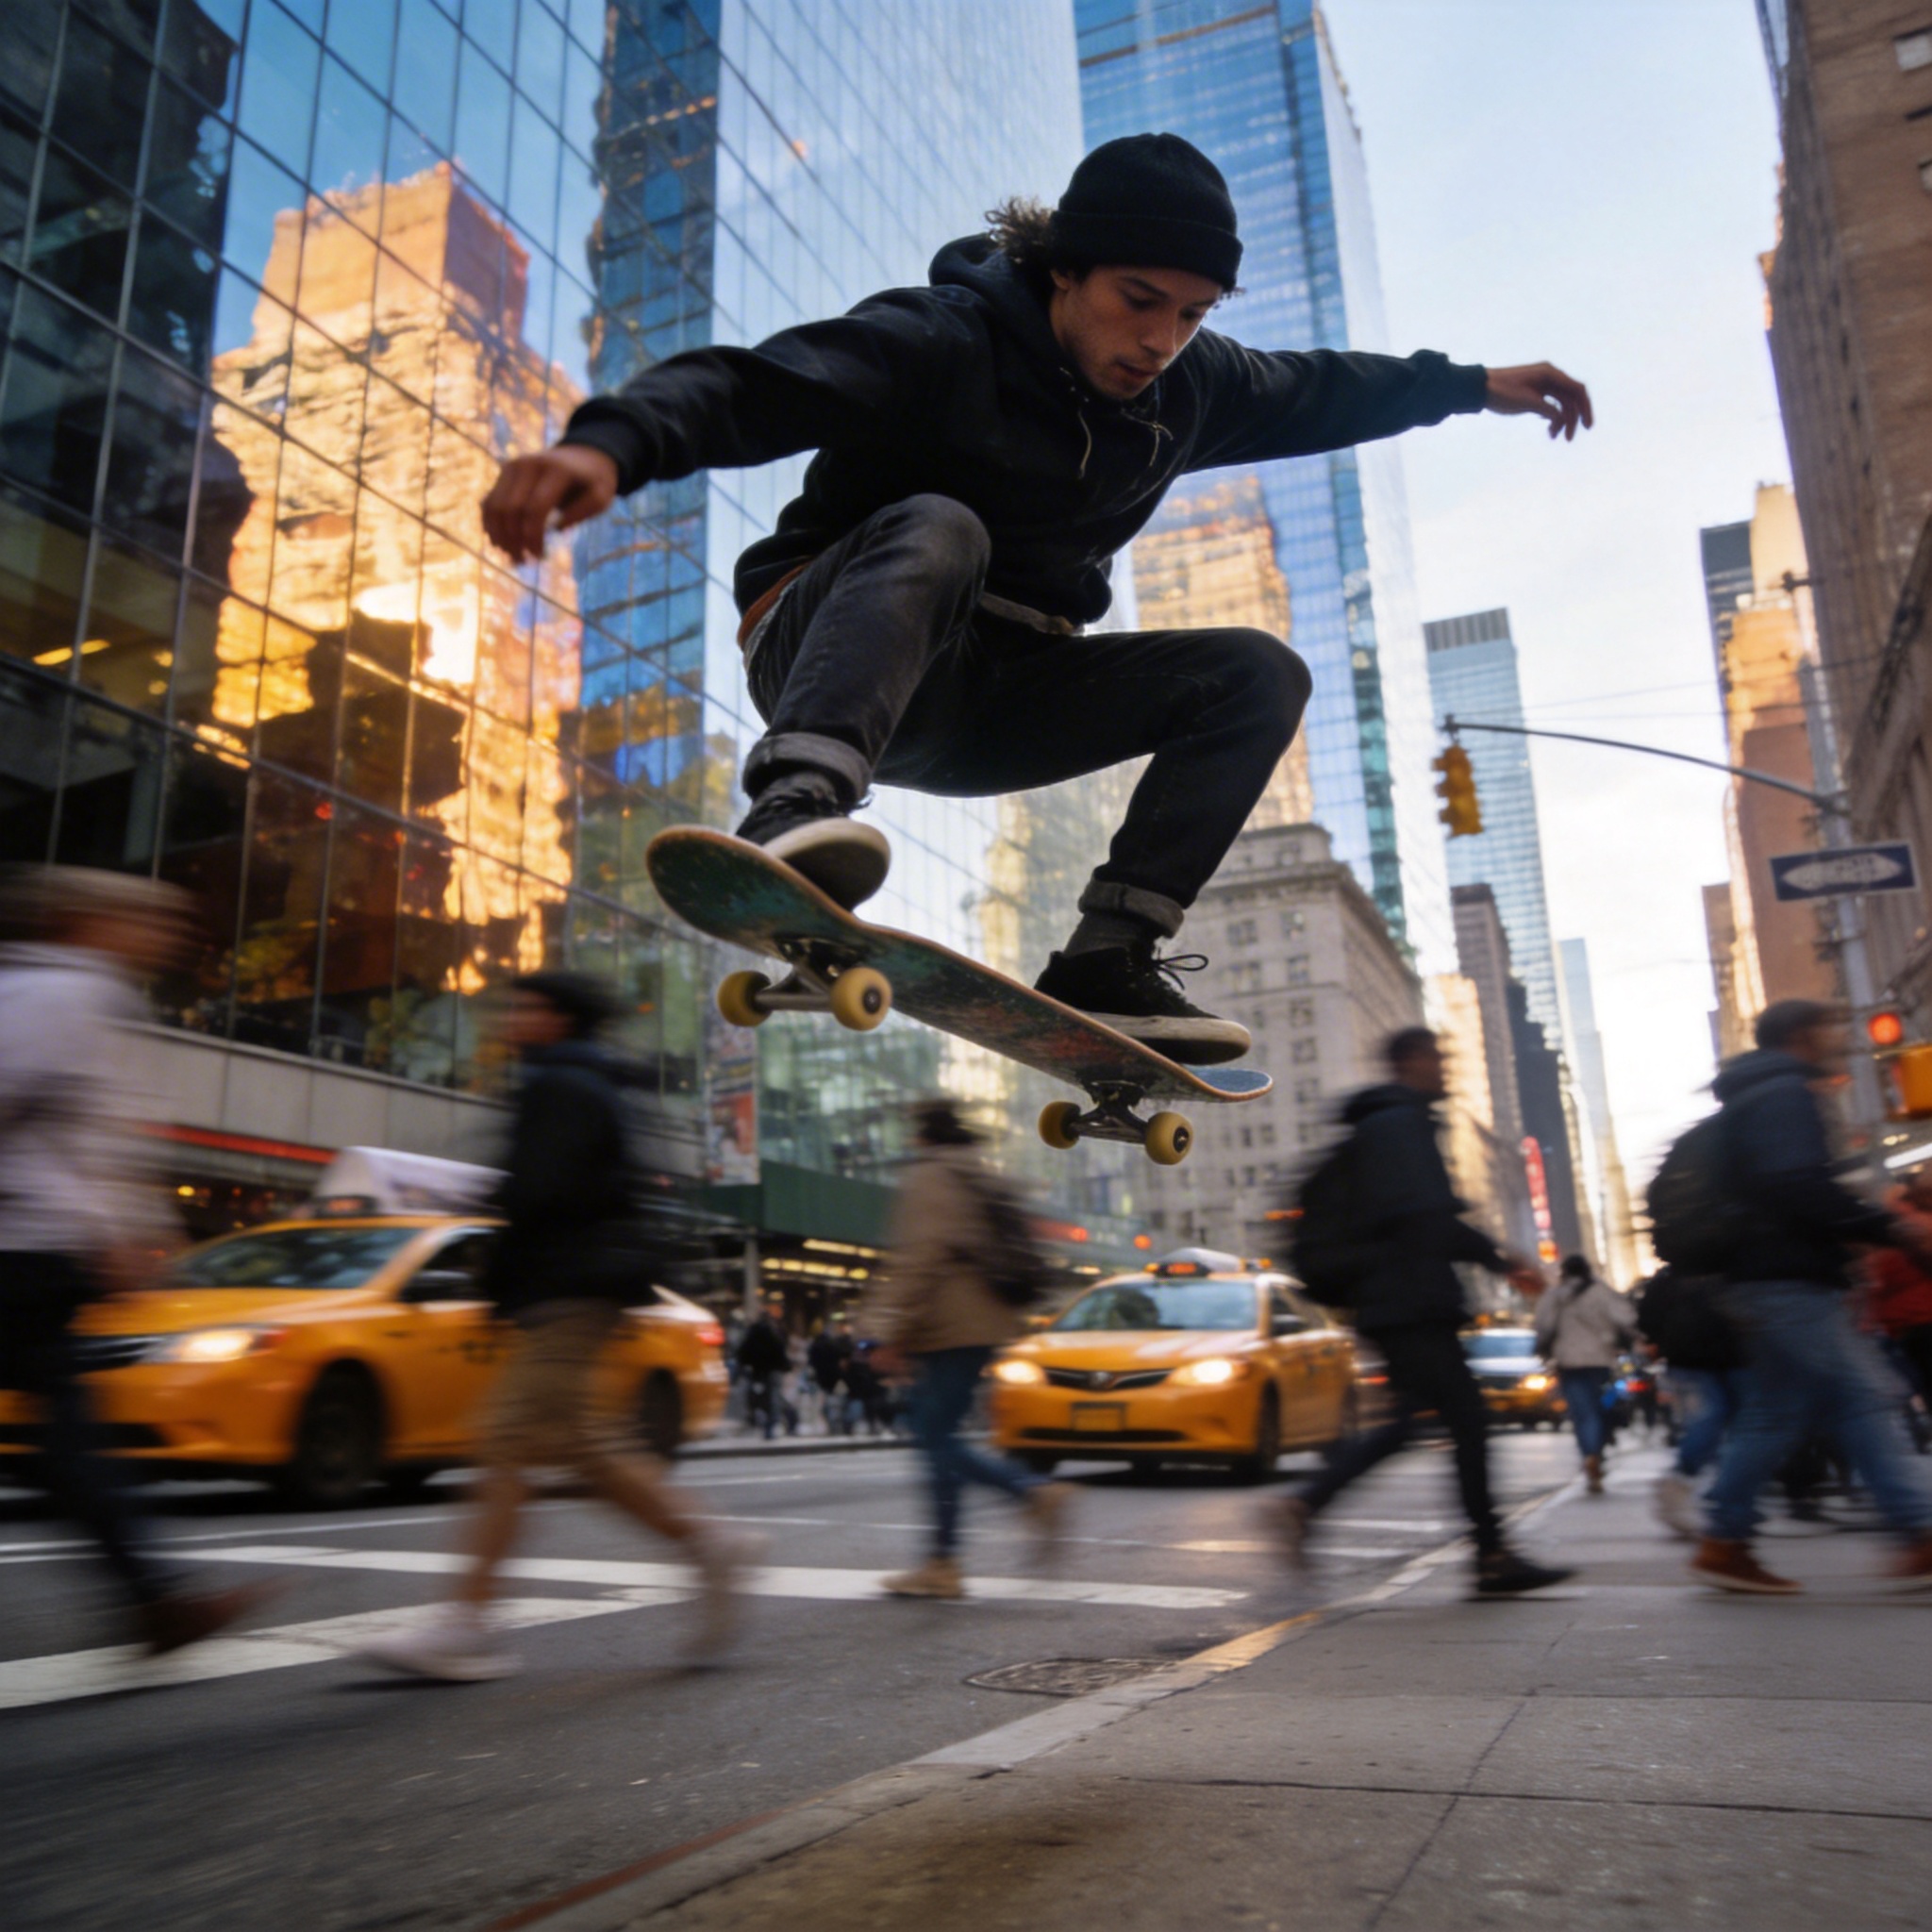
Skateboarder in motion on a busy New York City street, demonstrating dynamic scene generation.
The speed of generation is a key advantage, with Seedance 2.0 producing a video in 3-5 minutes on LibTV, without any queuing. This allows for rapid iteration, enabling creators to generate, review, and adjust content quickly.
LibTV Platform Enhancements
Alongside the Seedance 2.0 integration, LibTV has introduced several platform updates:
Image Editing Optimization: New mirroring and rotation capabilities allow users to adjust material composition directly within the platform, eliminating the need for external tools.
Subject Library Iteration: The subject library now supports video format uploads for voice, allows selection of voices from historical assets, offers AI-generated subject descriptions, and automatically creates three-view drawings for character consistency. This streamlines character creation for series content.
Skills Update: The
libtv-skillpackage has been updated, defaulting to the Seedance 2.0 environment for video generation when called via platforms like OpenClaw, Feishu ClawBot, or Claude Code.
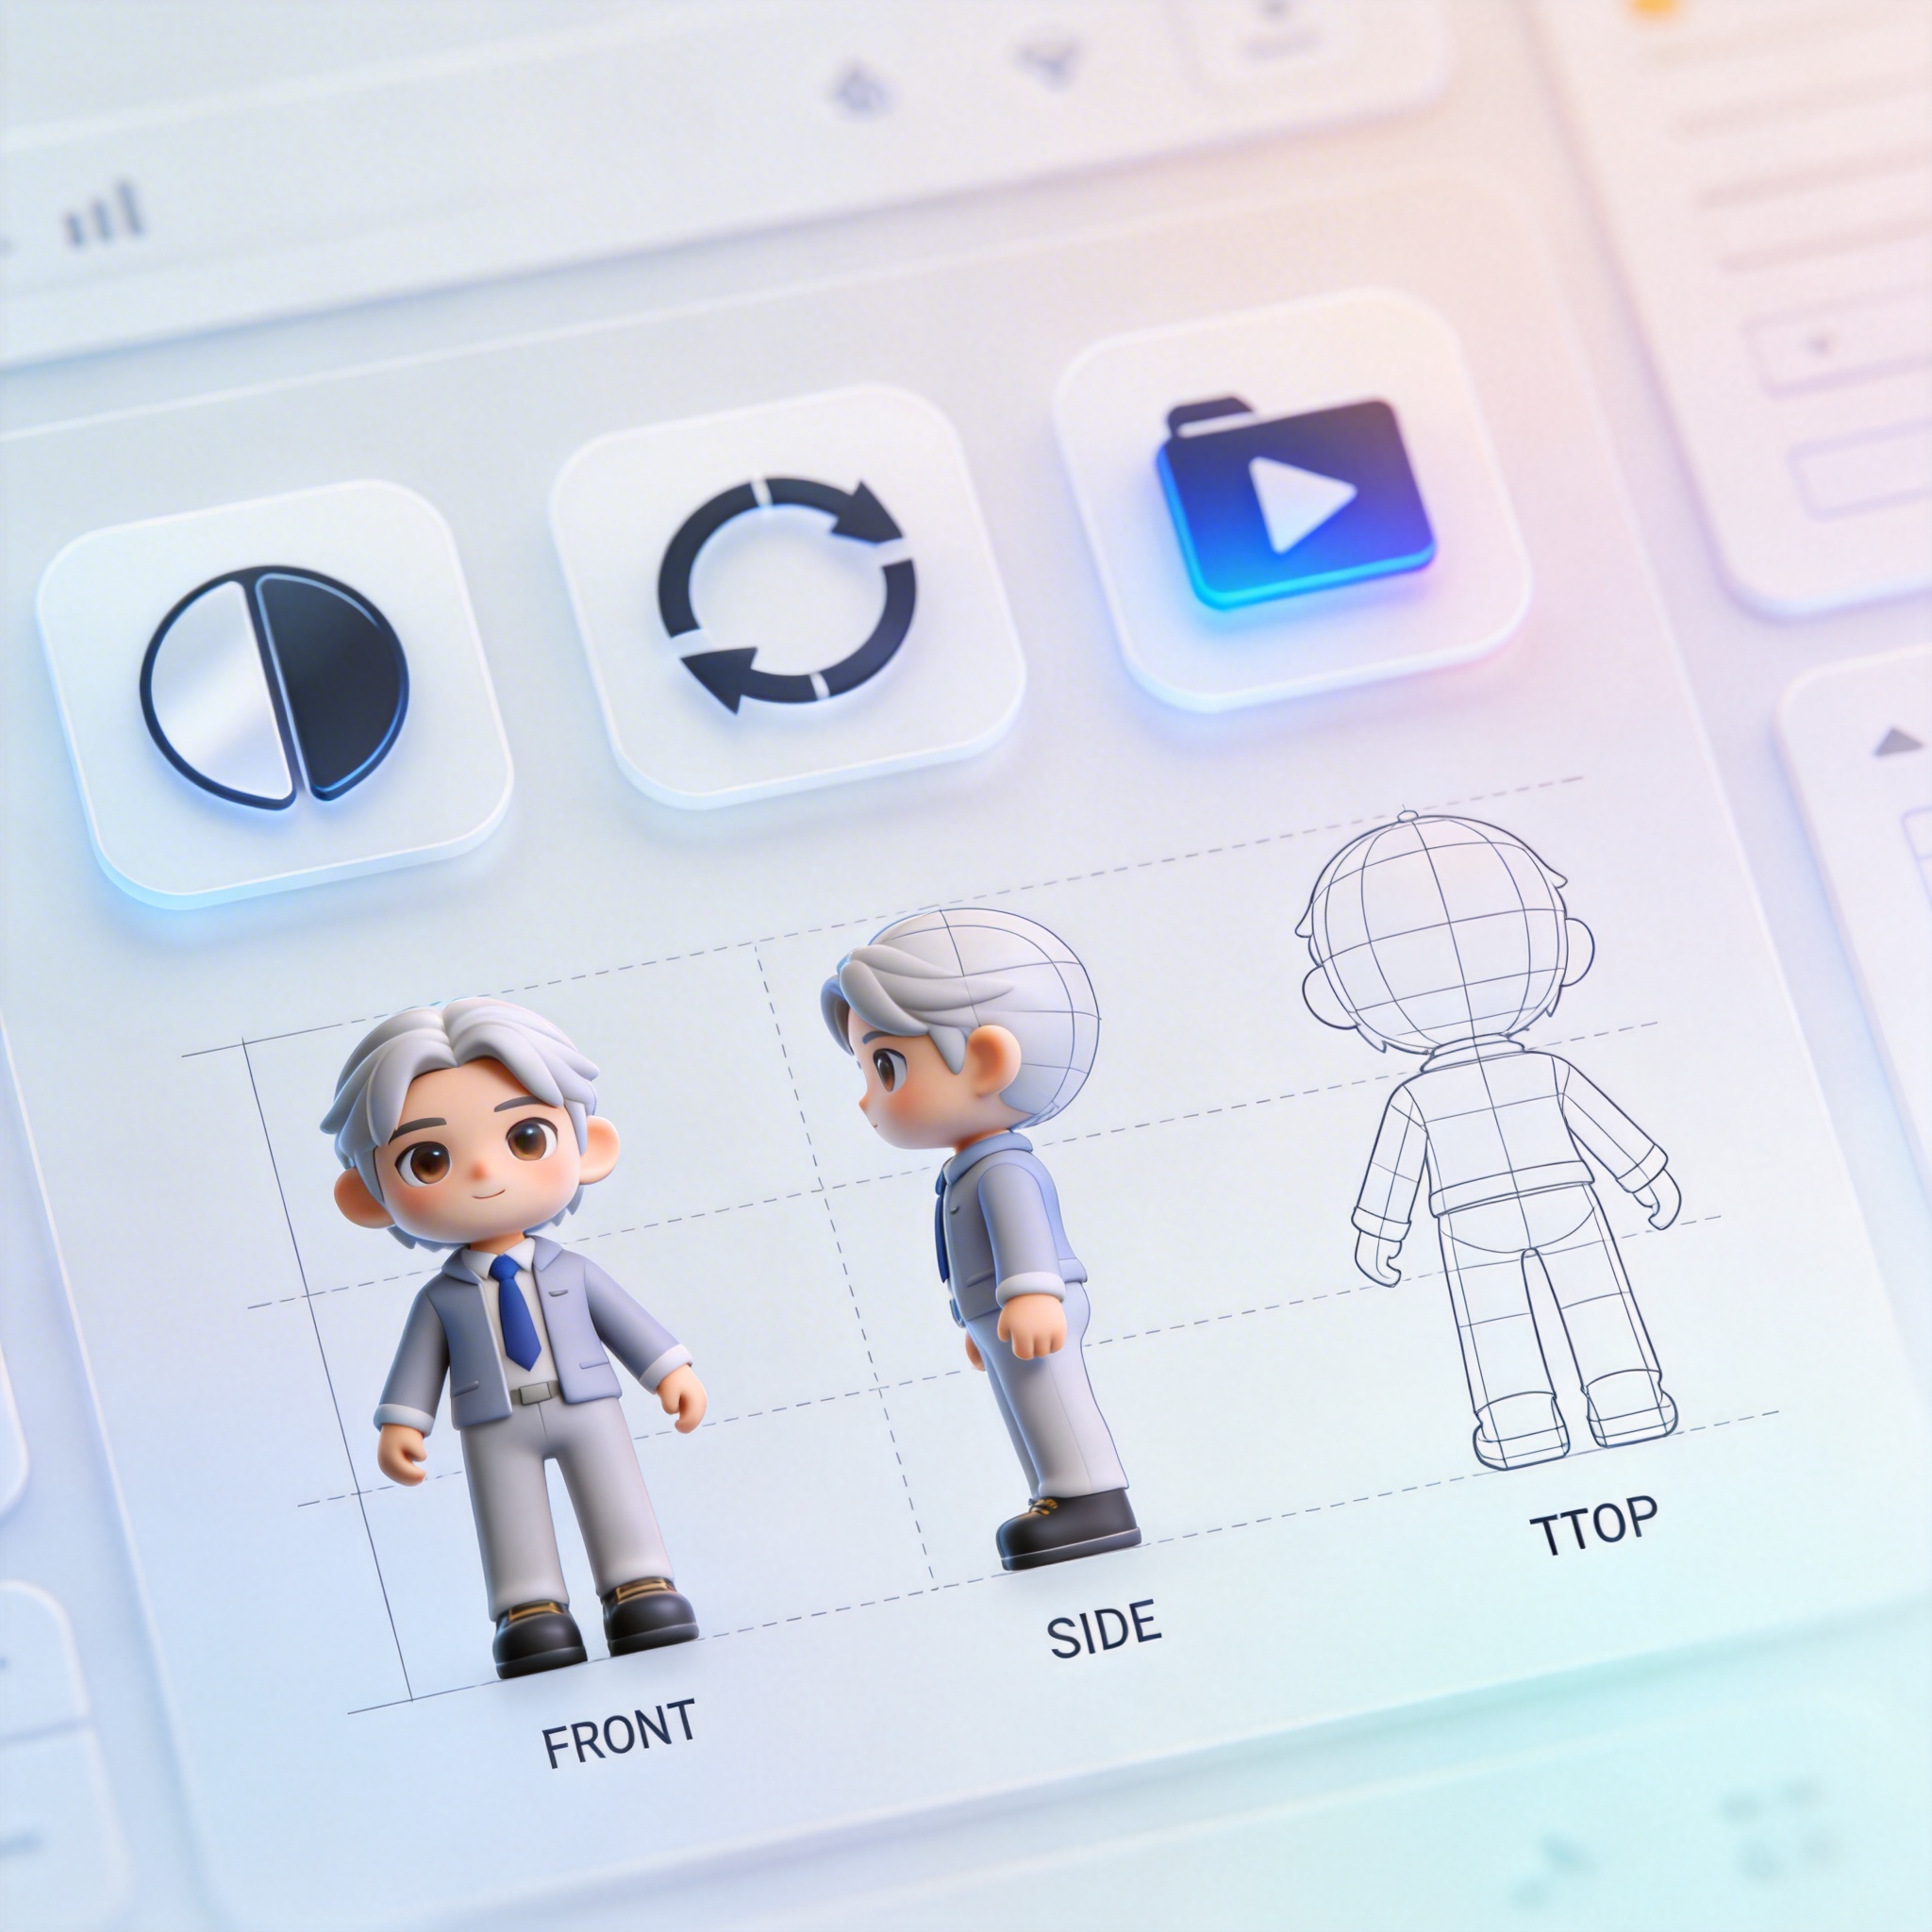
Digital interface showing image editing tools, video upload, and 3D character models, representing LibTV platform enhancements.
LibTV is also offering promotional pricing for Seedance 2.0, including free usage quotas with membership purchases and double points for first-time package purchases. The platform aims to reduce the cost of experimentation, allowing users to iterate more freely.
The integration of Seedance 2.0 and LibTV's workflow tools, including its canvas, script nodes, and Skills, positions the platform as a professional creative tool for video production.
Stay Ahead of the AI Curve
Join 50,000+ subscribers getting the latest AI tools, trends, and tutorials delivered to their inbox weekly.
No spam, unsubscribe at any time.