
Google Introduces Gemini 3.1 Flash-Lite Model, Offering High Speed and Lower Costs
Google has launched Gemini 3.1 Flash-Lite, a new model that achieves an output speed of 363 tokens per second and is priced at $0.25 per million input tokens. The model's benchmark performance reportedly surpasses that of some competitor models, including GPT-5 mini and Claude 4.5 Haiku.
The introduction of Gemini 3.1 Flash-Lite follows the performance of Gemini 3.1 Pro. The new model is designed for rapid output, with an output price of $1.50 per million tokens. For certain tasks, 3.1 Flash-Lite completed operations in 4 minutes compared to 33 minutes for Gemini 2.5 Flash, while consuming fewer tokens and achieving higher accuracy. The model supports converting various inputs, such as PDFs, text, images, video, and audio, into Markdown format. It also features a "particle forger" for simulating dynamic effects.
Developer interacting with a holographic interface showing code and data, representing API access.
Developers can access a preview version of 3.1 Flash-Lite via the Gemini API in Google AI Studio, and enterprise users can utilize it through Vertex AI.
Performance and Cost Efficiency
Gemini 3.1 Flash-Lite demonstrates an output speed of 363 tokens per second, comparable to its predecessor, Gemini 2.5 Flash-Lite (366 tokens/s), and faster than Gemini 2.5 Flash (249 tokens/s). When compared to other models, 3.1 Flash-Lite's speed is approximately five times that of GPT-5 mini (71 tokens/s) and 3.4 times that of Claude 4.5 Haiku (108 tokens/s). Grok 4.1 Fast operates at 145 tokens per second.
In terms of pricing, 3.1 Flash-Lite's input cost is $0.25 per million tokens, and output is $1.50 per million tokens. This makes it eight times more cost-effective than 3.1 Pro. For comparison, GPT-5 mini's output price is $2.00, Gemini 2.5 Flash is $2.50, and Claude 4.5 Haiku is $5.00, which is over three times more expensive.
Abstract infographic comparing AI model performance, speed, and cost metrics with glowing visual elements.
Benchmark Results
On the GPQA Diamond benchmark, which assesses scientific knowledge and reasoning, 3.1 Flash-Lite scored 86.9%. This score exceeds GPT-5 mini's 82.3%, Claude 4.5 Haiku's 73.0%, and Gemini 2.5 Flash's 82.8%.
For multimodal understanding, Flash-Lite achieved 76.8% in the MMMU-Pro test, outperforming GPT-5 mini (74.1%), Gemini 2.5 Flash (66.7%), Grok 4.1 Fast (63.0%), and Claude 4.5 Haiku (58.0%). In the SimpleQA Verified factual accuracy test, Flash-Lite recorded 43.3% accuracy, significantly higher than Gemini 2.5 Flash (28.1%), GPT-5 mini (9.5%), and Claude 4.5 Haiku (5.5%).
In multilingual capabilities, Flash-Lite scored 88.9% on the MMMLU test, surpassing Gemini 2.5 Flash's 86.6% and GPT-5 mini's 84.9%. For video understanding, the model achieved 84.8% in Video-MMMU, exceeding GPT-5 mini (82.5%) and Gemini 2.5 Flash (79.2%).
Multi-panel image showing AI capabilities: scientific reasoning, multilingual communication, and video analysis.
However, 3.1 Flash-Lite showed lower performance in some areas. In the LiveCodeBench code generation test, it scored 72.0%, while GPT-5 mini achieved 80.4% and Grok 4.1 Fast scored 76.5%. On Humanity's Last Exam, Flash-Lite scored 16.0%, comparable to GPT-5 mini's 16.7%, but lower than Grok 4.1 Fast's 17.6%.
Chatbot Arena Rankings
In the Chatbot Arena text competition, 3.1 Flash-Lite ranked 36th with an Elo score of 1432, placing it near o3 (1432 points) and GPT-5 High (1434 points). Grok 4.1 Fast Reasoning scored 1430 points. In the code arena, 3.1 Flash-Lite scored 1261, tying for 35th place. This is below Claude Haiku 4.5 (1308 points) and DeepSeek V3.2 (1321 points).
Adjustable "Depth of Thought" Feature
Gemini 3.1 Flash-Lite includes a "thinking levels" function, allowing developers to adjust the reasoning resources allocated to each task. This feature enables shallow thinking mode for high-frequency, low-complexity tasks like translation and data classification, optimizing for speed and cost. For complex tasks such as UI generation or multi-step instructions, a deep reasoning mode can be engaged to achieve performance comparable to larger models.
Abstract visual representing AI 'depth of thought' with glowing neural pathways expanding and contracting.
Real-World Applications
In practical tests, 3.1 Flash-Lite demonstrated its capabilities across various scenarios. For e-commerce, it can quickly populate prototype diagrams with product details. In data visualization, it can generate dynamic weather dashboards by integrating API data and historical analysis. The model can also build SaaS agents for automating multi-step tasks like customer ticket processing and order tracking. Additionally, it can analyze, tag, and classify large volumes of unstructured content, including images, documents, and user comments.
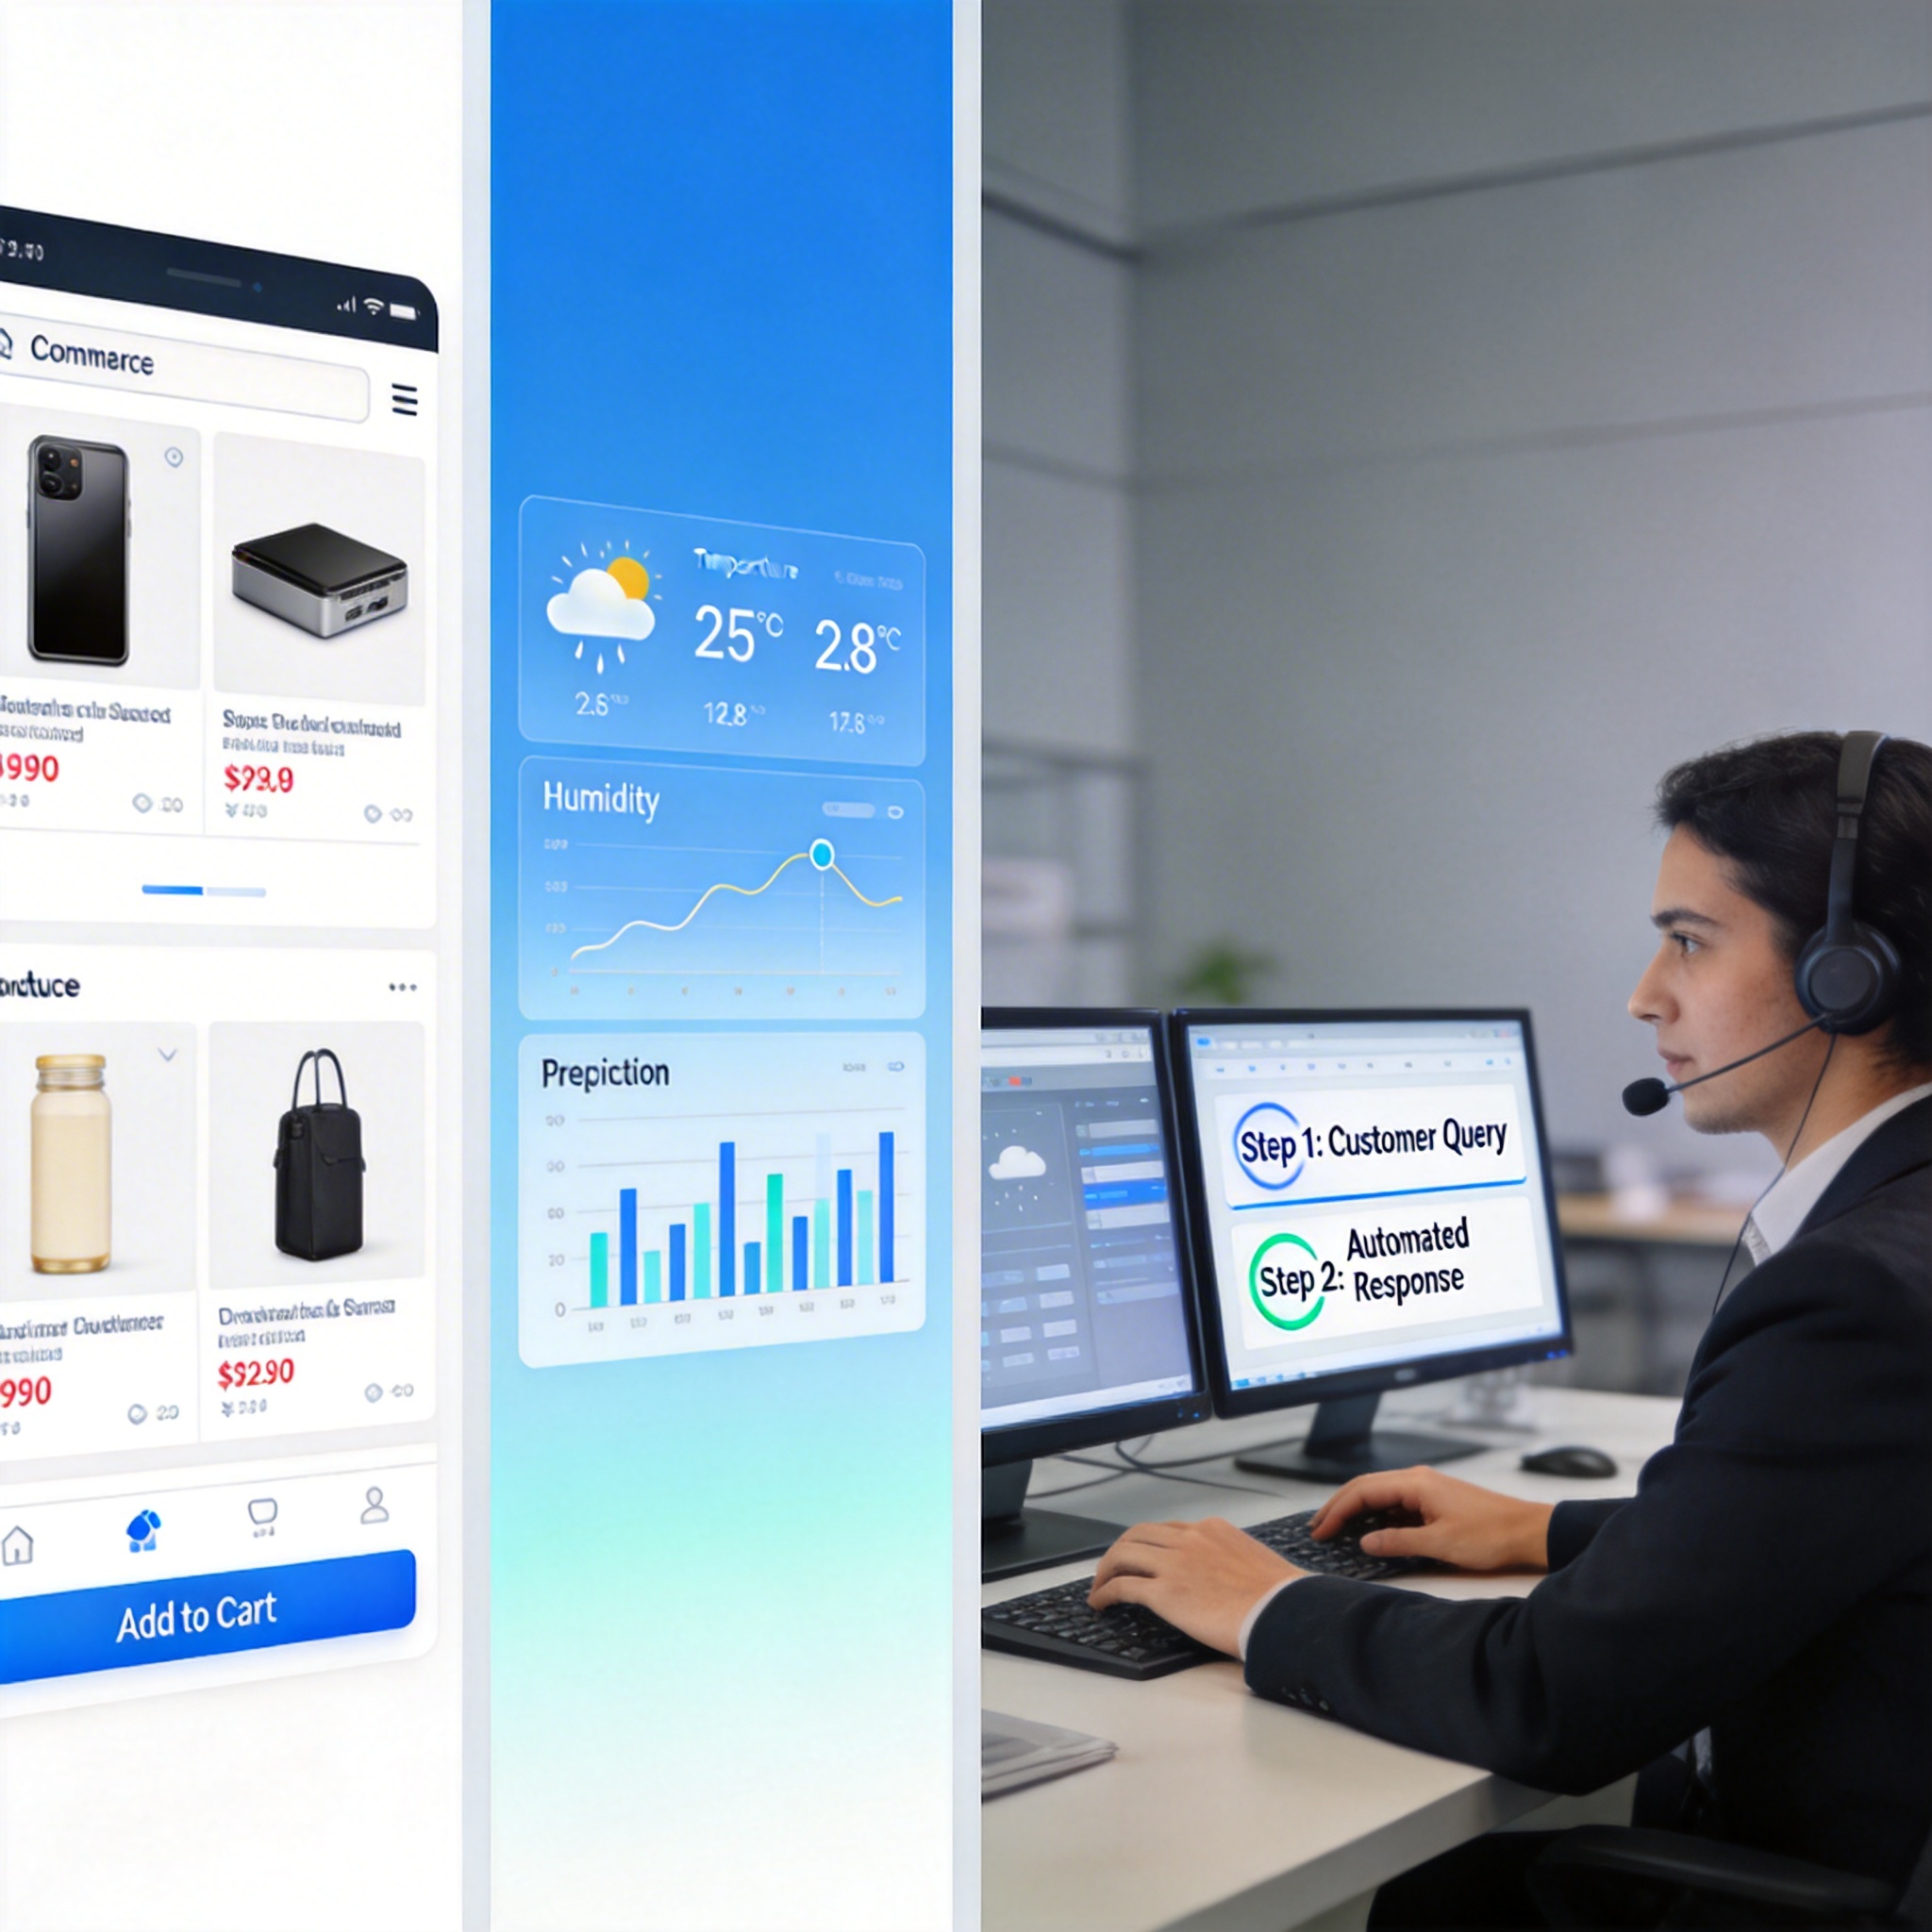
Three panels showing AI applications: e-commerce product population, weather dashboard, and automated customer service.
The release of 3.1 Flash-Lite indicates a shift in AI development towards models that balance performance with cost and speed. According to information reviewed by toolmesh.ai, the model aims to provide high-quality results at a reduced cost and increased speed, addressing a demand for efficient AI solutions in real-world product development.
Stay Ahead of the AI Curve
Join 50,000+ subscribers getting the latest AI tools, trends, and tutorials delivered to their inbox weekly.
No spam, unsubscribe at any time.